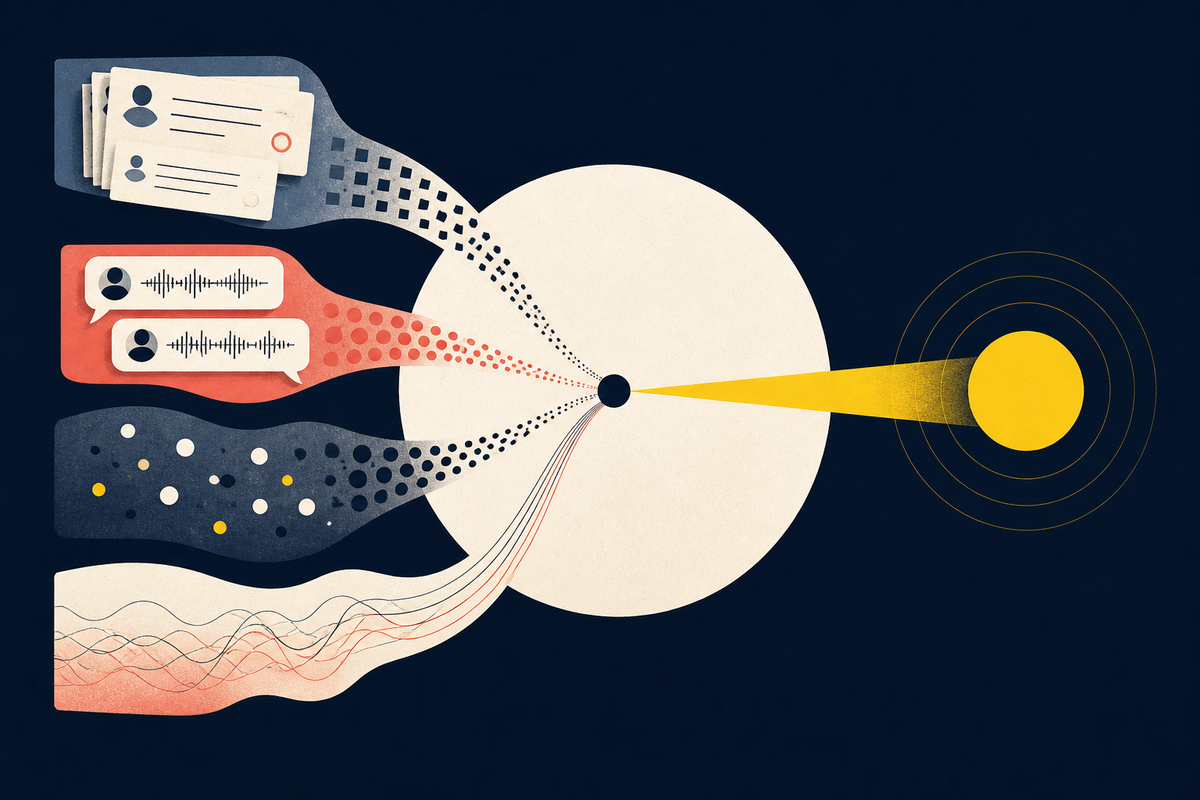
On a quiet Tuesday, a customer-experience lead sees satisfaction dip. A researcher remembers three interviews about navigation. A product manager finds a cluster of rage clicks. Someone pastes six links into Slack. By lunch, the team has evidence everywhere and an answer nowhere. The familiar response is to buy a platform. The better first move is to identify which part of that Tuesday is expensive.
Mopinion, Dovetail, Lyssna and PostHog are often pulled into the same evaluation because all four promise a closer view of customers. Their overlap is real: surveys, analysis, sharing and increasingly AI. Their centers of gravity are not. Mopinion begins with feedback at a digital touchpoint. Dovetail begins with accumulated customer evidence. Lyssna begins with a designed study and a participant. PostHog begins with a product event and adds the human answer beside it.
Start where the evidence enters
That difference changes daily usability more than a feature matrix suggests. A CX team running always-on website and app programs will recognize Mopinion's shape: build a branded form, trigger it at a relevant moment, watch responses arrive, then filter, chart, summarize and route them. Its product pages emphasize customizable dashboards, cross-tabs, a feedback inbox, recurring reports, sentiment analysis and action workflows. NPS, CSAT and CES fit naturally because the collection and reporting loop lives in the same place.
Dovetail asks a different question: what does the company already know, and can anyone find the proof? Its workspace organizes projects, highlights, documents, dashboards and imported conversations. The 2026 navigation update puts Home, Search, New and Favorites in a common sidebar. Pressing c creates, Command or Control plus K searches, and n opens notifications. Those are small details with a large adoption effect. A repository becomes useful when returning to it feels cheaper than asking a colleague to retell the story.
Lyssna is closer to the research workbench. It supports moderated interviews and unmoderated studies including usability tests, surveys, card sorts, tree tests, preference tests and five-second tests. Teams can bring their own audience or recruit from Lyssna's panel. That makes it useful before a product exists, when the question concerns comprehension or preference, and when behavior in production cannot supply the evidence.
PostHog is the most engineering-shaped workspace of the four. Surveys sit beside product analytics, session replay, feature flags, experiments, web analytics and other data tools. A researcher can ask a user why onboarding failed, then examine what that user did. A product team can target by properties or flags and compare answers with behavior. The trade-off is vocabulary. Events, properties, cohorts and funnels are powerful handles, but they add setup and cognitive load for colleagues who do not live in product analytics.
The winning platform is usually the one that removes the handoff your team repeats every week.YesPress analysis
Scores need a route back to reality
NPS, CSAT and CES answer different questions. NPS is generally used as a loyalty or recommendation signal. CSAT measures satisfaction with a product or interaction. CES asks how easy it was to complete a goal. Putting all three on one executive dashboard can make them look interchangeable. They are not. The useful work begins when a score is tied to timing, population, task, release and an open response that explains the rating.
This is where adoption affects analysis. If Mopinion is properly triggered on checkout, its response arrives with page, device and journey context. If PostHog is instrumented well, a survey answer can sit near the event path and replay. If interview findings live in Dovetail, a falling score can be tested against prior evidence instead of launching research from zero. If a Lyssna study reaches the intended participants and asks a clear follow-up, it can test the suspected driver directly.
One score, three levels of diagnostic value
Conceptual model, not measured performance. A score flags movement; segments locate it; comments, sessions and studies help explain it.
Driver analysis becomes credible when the team can compare the score with candidate causes and inspect original comments. Segmentation is the hinge. An overall CSAT line may stay flat while Android users on the newest app version fall sharply. A strong NPS may be carried by administrators while daily operators struggle. CES can improve for returning customers and worsen for new ones. Averages are calm because they are good at hiding arguments.
Mopinion's filters, cross-tabs and custom dashboards are built for this reporting work. PostHog's cohorts and event properties can make segments behavioral rather than merely demographic. Dovetail helps compare themes across a larger body of qualitative evidence. Lyssna helps construct a targeted study once the segment and suspected driver are known. In practice, mature teams may use more than one. The risk is not the number of tools by itself. It is whether identifiers, taxonomy and ownership survive the trip between them.
AI saves minutes and can blur uncertainty
Each product is moving AI closer to the work. Mopinion promotes automated categorization, sentiment, summaries and trend identification for incoming feedback. Dovetail's search can surface AI summaries for question-shaped queries, while Explore is designed for scanning evidence and broader patterns. Its AI-assisted insight drafts can turn findings into reports or product requirements. PostHog's AI reaches into analytics and product workflows. Lyssna uses AI not only after collection, for transcription and summaries, but during a study.
Lyssna's documented AI follow-up feature is the most concrete example of AI changing response quality. For long-text questions, the system assesses whether an answer is specific or thorough enough and may ask up to two contextual follow-ups. That can recover detail an unmoderated survey would otherwise lose. It also changes the instrument. Researchers should preview the behavior, inspect generated probes, and report that adaptive questioning was used.
Transcribe, group and summarize while preserving a clear path to the source.
Verify sampling, question wording, segments and contradictory evidence.
A polished summary that hides thin responses or uncertain causal claims.
AI is most valuable when it reduces clerical effort without severing provenance. A summary should be a door into comments, clips and sessions, not a replacement for them. Sentiment labels need spot checks. Themes need stable definitions. Trend alerts need enough volume and a consistent instrument. Otherwise the team can automate the appearance of certainty while the underlying response quality remains weak.
Measure the work around the work
For CX, insights and research leaders, productivity is not studies per quarter. It is the rate at which defensible evidence changes a decision without exhausting the people who gathered it. Watch time from question to first useful evidence, time from finding to stakeholder retrieval, repeated research, manual tagging, exports, and the share of insights with a named owner. Add adoption measures: weekly searchers, evidence viewers beyond the research team, saved or shared findings, and decisions linked back to sources.
Cognitive load appears in mundane places. A flexible dashboard demands design choices. A repository demands governance. A participant platform demands study craft. An analytics suite demands instrumentation. Search can reduce navigation but cannot repair inconsistent tags. Shortcuts help frequent users but barely matter to an executive who visits monthly. Collaboration features work only when permissions, notifications and review rituals are legible.
The buying test should therefore use a live question. Pick a recent issue, then run it end to end: trigger or recruit, collect, segment, inspect, synthesize, share, assign and revisit. Ask a researcher, a CX operator, a product manager and a skeptical stakeholder to complete their part. Count tab changes and exports. Notice where someone has to explain the interface. Check whether a claim can still be traced to a response. The rough edges in that exercise are more predictive than a polished demo.
Choose Mopinion when contextual feedback programs and operational CX reporting are the center. Choose Dovetail when fragmented knowledge and retrieval are the costly problem. Choose Lyssna when the team needs to create focused studies and reach participants. Choose PostHog when behavior and product delivery must sit next to the answer. Pair them only when the connection has an owner and the repeated handoff is worth removing.
The result is less romantic than a universal winner and more useful. A research stack should make the next honest question cheaper. It should let an answer keep its context as it moves from respondent to researcher to decision-maker. When that chain stays intact, scores become clues, AI becomes leverage and customer evidence gets a life beyond the meeting where it first appeared.
Sources and useful links
- Mopinion Insights & Actions and its guide to NPS, CSAT and CES
- Dovetail's updated workspace and shortcuts and Explore search
- Lyssna platform overview and AI follow-up documentation
- PostHog product platform and its practical guide to surveys, timing and behavioral context
- Workshop photograph by Vitaly Gariev on Unsplash