There is a particular kind of confidence that comes from watching an AI voice agent complete a demo. It greets the caller. It finds the right answer. It closes with a pleasant goodbye. Then a real person phones in from a noisy train, changes the subject twice, interrupts the reply and asks for a refund the policy does not allow. The demo has ended. The actual test has begun.
- Coval tests voice and chat agents with simulated conversations, then checks their behavior in production.
- Founder Brooke Hopkins brought evaluation experience from Waymo, where software is tested against many journeys before anyone rides along.
- Customers include Zoom, Deepgram, Phonely and Krew; Coval says more than 60 organizations use its platform.
- Published plans start at $100 a month, with usage measured in simulation minutes and monitored calls.
Coval is a San Francisco software company built around that gap. Its platform sends synthetic callers through a voice agent, scores the results, watches real calls after launch and lets people review the cases an automated judge may misunderstand. It sells to teams building customer-service and other conversational agents, including those in finance and healthcare, where a cheerful wrong answer can be expensive.
The road led to the phone line
Brooke Hopkins, Coval's founder and chief executive, once led evaluation job infrastructure at Waymo. Her team built tools for launching and running evaluations of autonomous vehicles. A car cannot be judged by a clean trip down a quiet street. It has to meet strange intersections, unexpected pedestrians and a near-infinite supply of human decisions. Hopkins saw a related problem in AI agents: the machine has a destination, but the path depends on what a person does next.
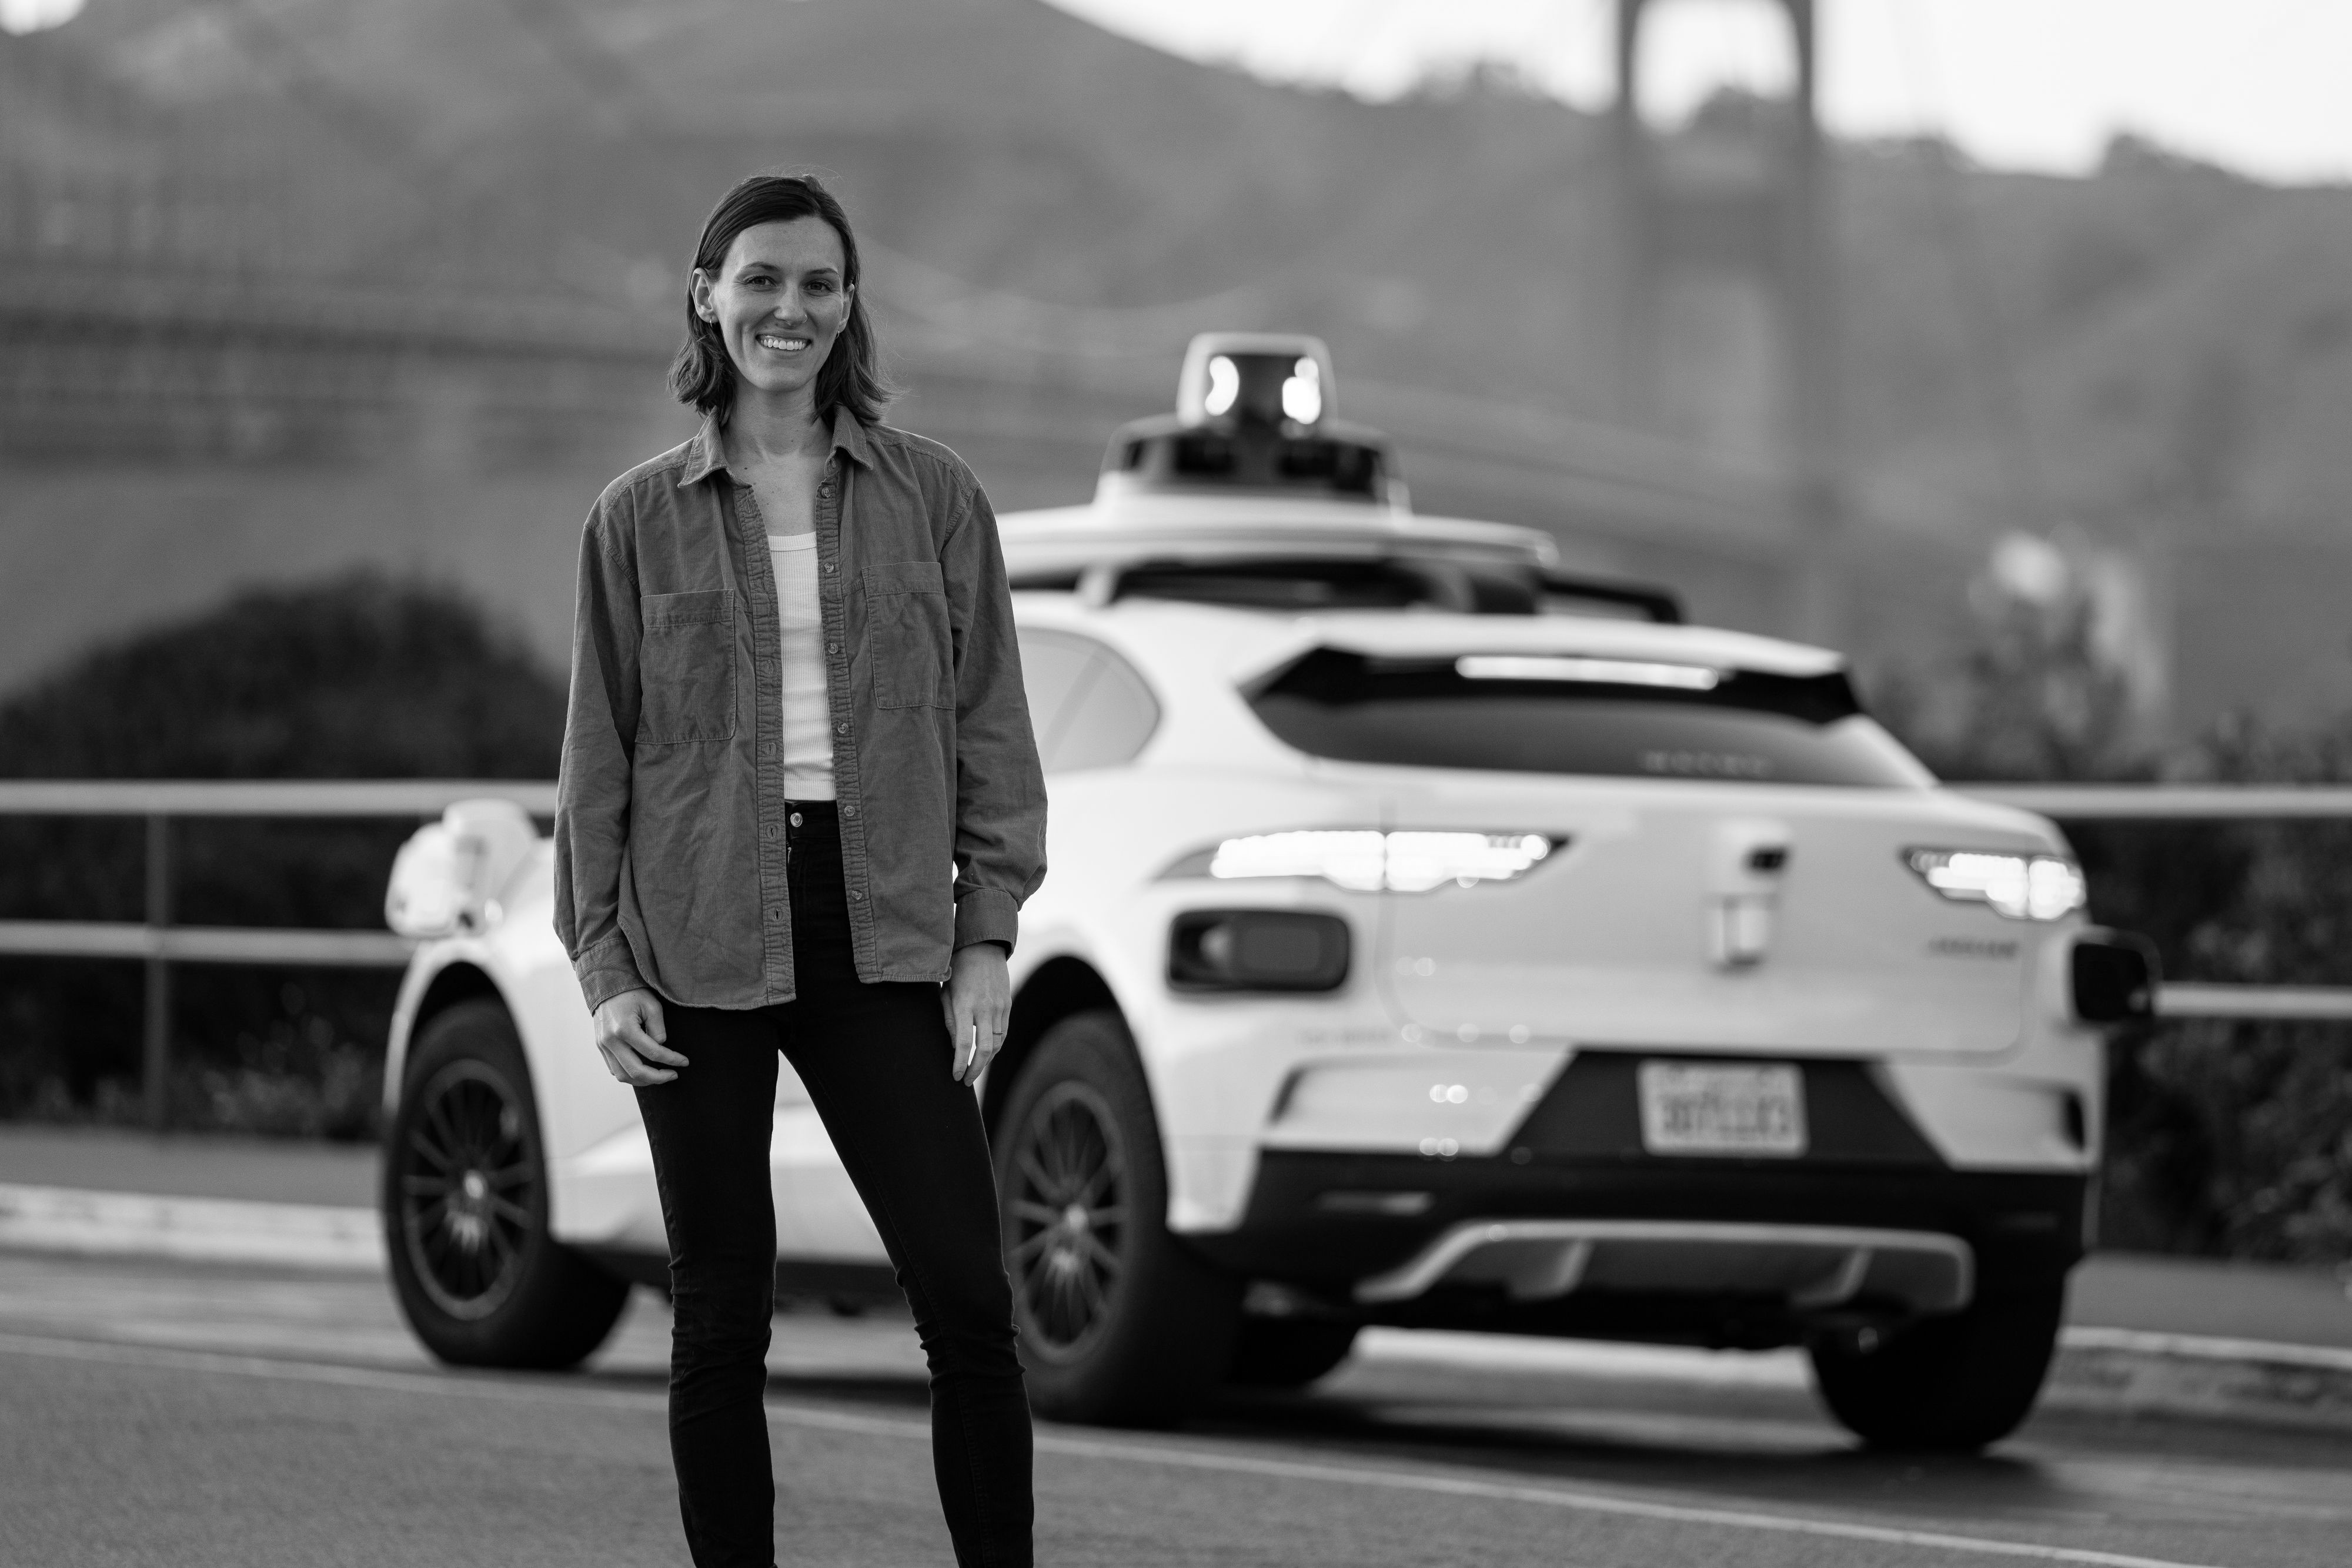
Coval's founding announcement in 2024 came with $3.3 million in seed backing. Its proposition was already specific: turn conversations into scenarios, run them against an agent and measure more than whether its final sentence sounds reasonable. A voice system can produce the correct words while taking too long to speak, mishandling an interruption, losing a tool result or failing to hand a caller to a person. A transcript alone may miss the crime scene.
“Before starting Coval, I led the evaluation job infrastructure team at Waymo.”Brooke Hopkins, on Coval's company page
Give the agent a difficult customer
The product follows a loop. Before deployment, a team gives Coval a set of scenarios: a caller trying to verify an account, say, or one who changes an appointment, speaks over the agent and asks an unrelated question. Coval runs simulated conversations against different personas and variations. The team can inspect task success, latency, turn-taking, compliance and tool-call accuracy. If a prompt or model changes, the tests can run again, including through developer tools and CI workflows.
After launch, Coval evaluates production conversations against the same quality bar. Human reviewers can label calls that require context or judgment, and those labels can improve the automated metrics. A failure found in the wild becomes a candidate for tomorrow's regression suite. The method is almost stubbornly unromantic. It asks teams to keep a record of how their agent goes wrong, then make the agent prove it has learned.
That is also where Coval sits in the market. Vapi and Retell provide the infrastructure to build and run voice agents, and both have added native evaluation features. Hamming and Cekura sell specialist testing tools. An enterprise can also build its own QA stack. Coval's claim is that a dedicated, cross-platform evaluation layer - with simulation, monitoring and human review together - gives product, engineering and operations teams a shared definition of a good call. It is a useful claim, though any buyer should test it on their own conversation set.
A bank's QA problem, in miniature
Krew, which builds voice agents for credit servicing, offers the clearest public account of the problem Coval solves. Krew already had performance checks and basic quality assurance. What it lacked was a practical way to scale tests for perceived latency, interruption handling, turn-taking and compliance. In Coval's case study, Krew says it got testing running in days and made the platform part of its engineering routine within two months. It reports more than 10,000 evaluations a month.
Krew's point was not simply to run a larger test count. In credit servicing, an agent may be expected to verify identity, follow a particular workflow and avoid giving the wrong instruction to a caller who could act on it. A stable benchmark also lets a team see whether a later update improved the call or merely changed it. Krew says it can show independent evaluation reports to enterprise customers during procurement. QA became something the sales team could carry into the room.
Phonely found a more intimate use. Its no-code voice-agent product integrates Coval's simulations. As cofounder Will Bodewes described it, a call that went well can be saved as a simulation test. The next change must still handle that conversation. This sounds obvious until one remembers how often software teams celebrate a fix without preserving the failure that made it necessary.
The meter is running
Coval has a conventional subscription business with an unusually revealing meter. The published Starter plan costs $100 monthly and includes 100 simulation minutes and 1,000 monitored calls. Growth is $500 monthly for 1,000 simulation minutes and 10,000 monitored calls. Enterprise starts at $4,500 monthly with custom allowances. The pricing page also publishes overage rates. Seats are unlimited across plans, suggesting that Coval wants the bill tied to the work being checked rather than the number of people arguing over the result.
That cost only makes sense beside the alternative: staff listening to calls, engineers building test machinery and customers discovering the defects first. For a team with a handful of experimental calls, a spreadsheet and careful listening may suffice. For one running thousands of consequential conversations, repeatable coverage begins to look like infrastructure. Coval's customers are buying a way to make quality less dependent on whoever happened to hear yesterday's worst call.
A public wager on measurement
In June 2026, Coval announced a $28 million Series A led by Norwest, with Base10 Partners, Twilio Ventures and Y Combinator participating. The company said it had raised $31 million in total and would expand sales, solutions engineering, simulation, integrations, human review and monitoring. Zoom and Deepgram were named in the announcement. A partnership with Vapi links Coval's evaluations to calls managed on Vapi's platform.
Coval has also published voice-model benchmarks and an open-source runner. Its methodology describes fixed datasets, shared samples across providers and explicit caveats about what the scores can and cannot tell you. That matters because an evaluation company must eventually submit its own measurements to inspection. The public benchmarks do not prove a particular agent will handle a particular customer. They do show the company's instinct: make the test reproducible enough for someone else to argue with it.
The lesson outside Coval's customer list is portable. Start with a real failure. Turn it into a scenario. Include the distracting details that made it real: the pause, the interruption, the wrong account, the policy exception. Run it before the next release, and compare the result with calls after release. A voice agent that sounds human is a nice trick. One that can repeatedly finish the job, under conditions its creators did not script, is a product.