Before Parag Agrawal had to think about who would own Twitter, he was thinking about what should appear in its timeline. Before that, he was helping friends build storage and streaming services on a hostel network at IIT Bombay. The audience has changed considerably since the hostel. The recurring problem is recognisable: information is somewhere over there; someone needs it over here; the connection ought to work.
His latest company adds a complication. The someone may be software. Agrawal, founder and CEO of Parallel Web Systems, is building infrastructure for AI agents that search, read and work across the internet. These visitors have little interest in a handsome homepage. They want the answer, the evidence and preferably a bill that makes sense.
For an engineer whose time at Twitter involved the clamour of human conversation, it is a curious next assignment. He is now designing for customers that do not need a conversation at all. Yet the turn makes more sense when his career is viewed from the machine room, where he spent years before the chief executive's office made him a public figure.
A gold medal, then the hostel intranet
Agrawal was born in Ajmer, India, in 1984 and went to school in Mumbai. In 2001, he won a gold medal at the International Physics Olympiad in Antalya, Turkey. The Indian delegation returned with three golds and two silvers. Long before his name appeared in business headlines, it appeared on a results table for solving physics problems.
He graduated from IIT Bombay in 2005 with a degree in computer science and engineering. Ask an institution to remember a graduate and it will usually reach for the degree. Ask the graduate and something more useful may emerge. Agrawal's recollections include building shared storage and streaming services with friends over the hostel intranet, and spending time with close friends near Vihar Lake behind Hostel 4.
There is something pleasingly ordinary about that combination: make a thing work, then go and sit by the lake. The institutional biography includes his own compact statement of belief: “The whole can be much greater than the sum of parts.” It is an apt motto for someone whose student memory puts the friends inside the engineering story.
A dissertation with a useful title
After IIT, Agrawal moved to Stanford for graduate work in computer science under Jennifer Widom. His dissertation, published in 2012, was called Incorporating Uncertainty in Data Management and Integration. The title has acquired an accidental second life. Uncertainty would become an ample feature of his professional circumstances, although the research concerned databases rather than corporate takeovers.
The technical question deserves its own attention. A database can look reassuringly definite: rows, columns, entries in their proper places. Information collected from different places is less obedient. Research into uncertainty addresses the gap between a tidy representation and what is actually known. The title alone supplies a useful corrective to the idea that all computer science consists of making computers sound certain.
He also worked on large-scale data management with collaborators at Microsoft Research, Yahoo Research and AT&T Labs. By the time he joined Twitter in 2011, he had spent years on problems beneath the visible interface. That background helps explain why a familiar public name can have a much less familiar technical history.
Eleven years behind the timeline
At Twitter, Agrawal worked across advertising and consumer engineering. He helped scale advertising systems and improve the relevance of the home timeline. He became the company's first Distinguished Engineer, then chief technology officer in October 2017. His remit included technical strategy and advancing machine learning across the business.
Those responsibilities brought him close to a question that social networks make unavoidable: of everything a service could show, what should this particular person see? Getting a system to deliver content is one problem. Deciding which content deserves delivery is another. Twitter's engineering work put him at the intersection of the two.
In November 2021, Twitter's board unanimously appointed him CEO, succeeding Jack Dorsey. The announcement elevated a long-serving technical executive into a role that was observed in public, minute by minute. A career built through internal responsibility suddenly had an audience far beyond the company.
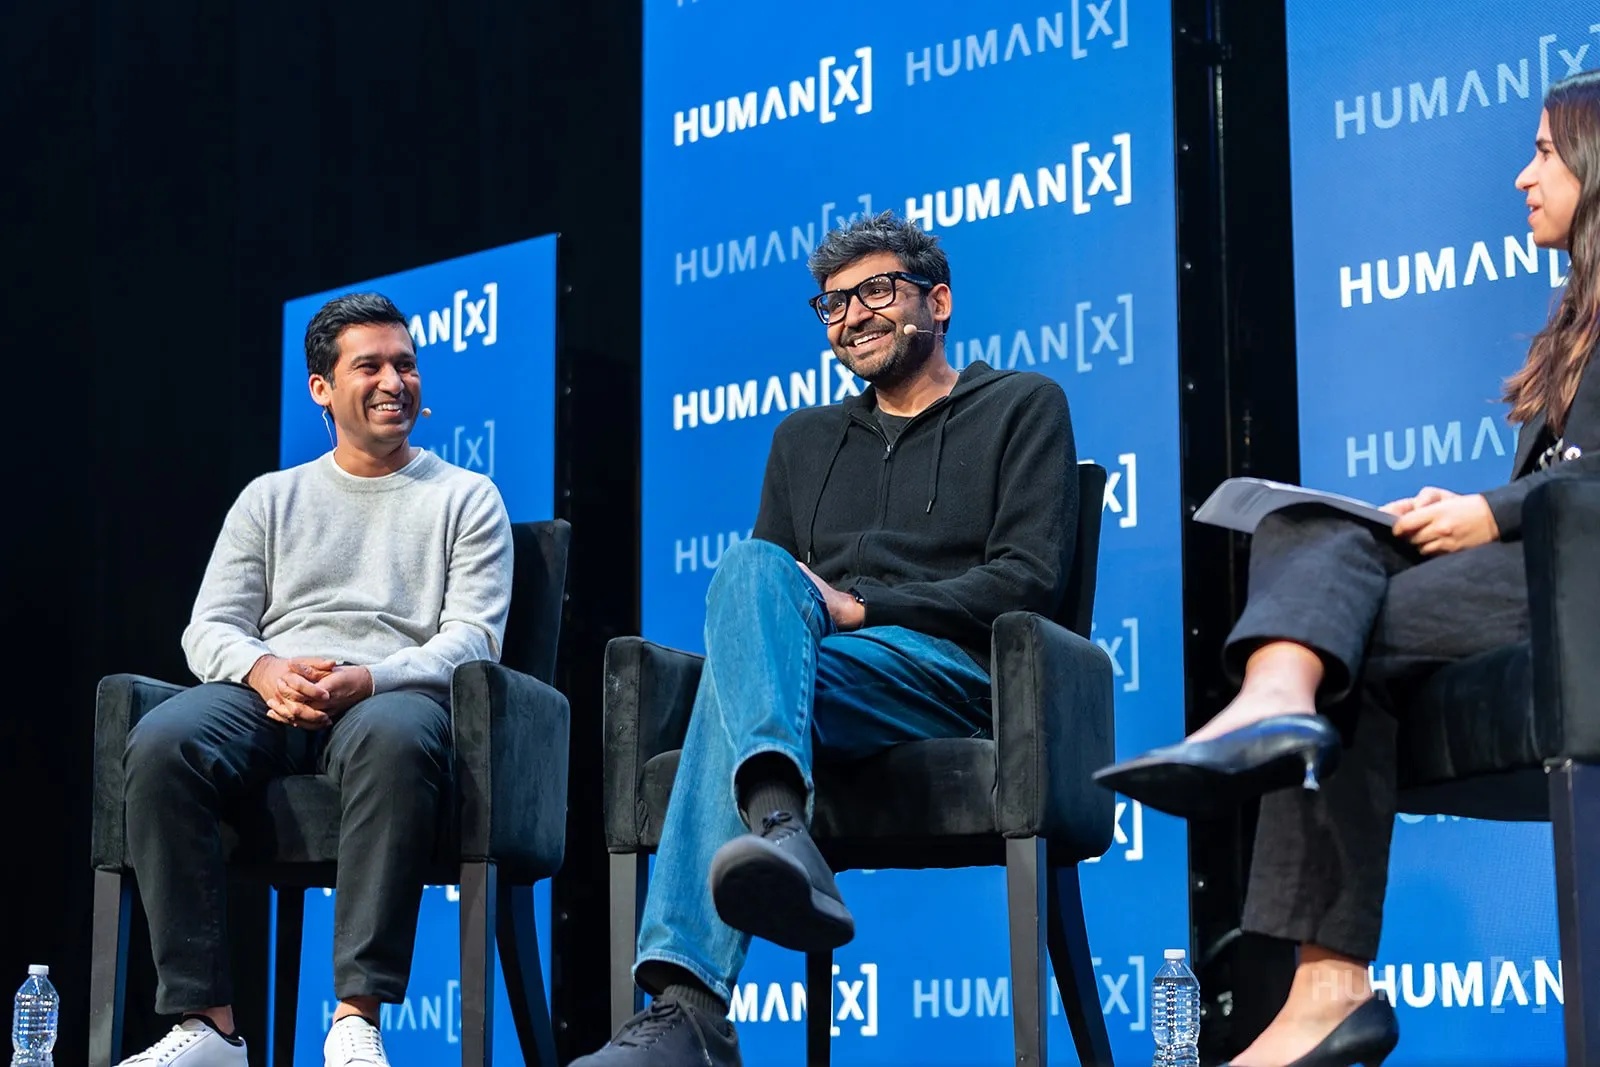
His tenure ran into the Musk acquisition almost immediately. By May 2022, Agrawal was pausing most hiring and changing senior leadership while the proposed transaction hung over the business. The company's growth and revenue targets had come under pressure. He was trying to run an organisation whose ownership, direction and employees' expectations were all in motion.
On October 27, 2022, Elon Musk completed the acquisition and dismissed Agrawal. His time as CEO had lasted less than a year. It was a decisive ending to eleven years at the company, and an unusually public one. The exit remains a fixed point in his biography. The work that followed gives it some competition.
Start again. Change the customer.
Agrawal founded Parallel in 2023. Its public API launch came in August 2025, offering search tools and deeper research services to developers. A company can use these services inside its own software, allowing an agent to retrieve current web information while carrying out a task. The interface is a request from one program to another.
The distinction matters for his story. At Twitter, Agrawal helped operate a service with an established mass audience. At Parallel, he began building around a customer whose habits were still emerging. Experience could help with engineering; it could also tempt him to solve yesterday's problem with unusual efficiency.
He has described having to unlearn lessons from Twitter. In his August 2026 conversation with Sequoia's Sonya Huang and Andrew Reed, he contrasted Twitter's enormous, established feedback loops with the uncertainties of a young company building for agents. His blunt formulation for search was: “human click data is a bug.” That is a statement about the signals his new customer needs, rather than an objection to human beings.
“Human click data is a bug.”
Parag Agrawal, on search built for agents
A person may click a promising link and abandon it. An agent may need several documents to finish one piece of work. Training a system to predict the click and training it to support completion can reward different results. Agrawal's career now contains both sides of that distinction. It gives his argument a useful edge: he has worked on the machinery whose assumptions he is reconsidering.
Conceptual illustration of an agent research workflow.
The team has to believe before the market arrives
In a discussion with Madrona's Jon Turow and fellow infrastructure founder Nikita Shamgunov, Agrawal described the difficulty of hiring before the customers he imagined had fully appeared. The team needed conviction about that future, and enough adaptability to move when opportunities became concrete. He linked that need for speed to building a team that worked together in person.
His hiring framework allows for two sorts of contribution: people who introduce risk and potential upside, and people who can help concentrate that risk into something workable. That is a more revealing description of his management thinking than an adjective attached to his personality. He is interested in how colleagues change one another's effectiveness.
He has also described using agents for his own company analysis and for drawing together feedback from customer calls. These are practical experiments for a founder selling infrastructure to other experimenters. They put him close to the awkward details: whether the output is useful, whether the evidence supports it, and how much correction the human still has to do.
Who pays for the answer?
The next problem follows the information back to its origin. Parallel's founding statement argues for an open web where contributions can be tracked and participants can earn according to the value they add. A useful answer depends on someone having done the reporting, maintained the record or assembled the data. The agent's convenience does not settle that person's invoice.
In May 2026, Parallel launched Index, a platform intended to help participating content owners see how agents use their material and receive compensation for its contribution. Launch partners included The Atlantic, Fortune Media, PitchBook and independent publications. The proposal estimates a source's contribution using Shapley values, a concept from game theory.
The underlying question is intelligible without the mathematics: how much less useful would the work have been without this information? Parallel proposes paying according to contribution to agent work, rather than simply counting access or citations. That remains an economic model to put into practice, with publishers and data owners whose interests need to hold together over time.
For Agrawal, it connects the search problem to the conditions that make search worthwhile. A system can become very good at finding material while the business of producing that material becomes less attractive. His new company has chosen to make that tension part of its remit.
Back to the machinery
The resources behind the attempt have grown. Parallel announced a $100 million Series A in November 2025, co-led by Index Ventures and Kleiner Perkins. In April 2026 came a $100 million Series B led by Sequoia, at a $2 billion valuation, bringing total funding to $230 million. Those figures describe the company, rather than Agrawal's personal wealth.
His current work also has the less theatrical texture of infrastructure. Parallel introduced Fast search mode in August 2026, with a published price of $1 per 1,000 requests. On October 22, it announced European data residency for Search and Extract. Price, processing location and the terms of a request are hardly glamorous subjects. For software that another business must depend on, they are consequential ones.
Agrawal's public biography will always include the short, turbulent chapter at Twitter's helm. His present undertaking makes room for a longer view: the student building services with friends, the researcher studying uncertain data, the engineer choosing what information reaches whom. Now he is working on what happens when the next reader is a program. The connection still has to work. This time, he is also trying to make sure the people at the other end get paid.