There is a robot across the street from Physical Intelligence's office that spends its day assembling chocolate boxes. Another, inside the office, responds to a coffee order placed through Slack. They are peculiar colleagues. They also explain what Sergey Levine has been trying to build for more than a decade. A box is never quite the same box. A cup sits a little differently. The world keeps moving after the video crew leaves, and a machine meant to work in it has to keep moving too.
Levine described both experiments in 2026. Neither is presented as a finished commercial operation. Each gives a robot a job it can attempt repeatedly while the people around it see what goes wrong, what improves and what the next lesson should be. For Levine, the work itself is part of the curriculum. A robot cannot learn much about a chocolate box by seeing it only from the angle in a neat demonstration.
It is an oddly practical destination for someone who entered graduate school fascinated by computer graphics. Yet the path from an animated character to a robot folding a shirt is shorter than it first appears. Both must move in a world governed by consequences. One world can be reset with a click. The other contains coffee.
The animated beginning
At Stanford, Levine studied computer science and worked on the movement of simulated bodies. His 2009 master's report was about modeling body language from speech in natural conversation. His PhD, completed in 2014 under Vladlen Koltun, concerned motor skill learning and trajectory methods. In an interview years later, Levine recalled being drawn to video games and movies, then to the intelligence implied by believable character animation. The question changed gradually: what would let a character choose and learn its behavior, rather than merely look convincing?
The answer led him out of the screen. After the doctorate, he joined Pieter Abbeel's robot learning lab at UC Berkeley as a postdoctoral researcher. Levine has said he had not worked on robotics before 2014. He brought methods from graphics and machine learning into a room full of physical machines, where a poor decision could send an arm past the object it meant to grasp. Moving from simulation to a lab bench was less a change of subject than a stern new examination.
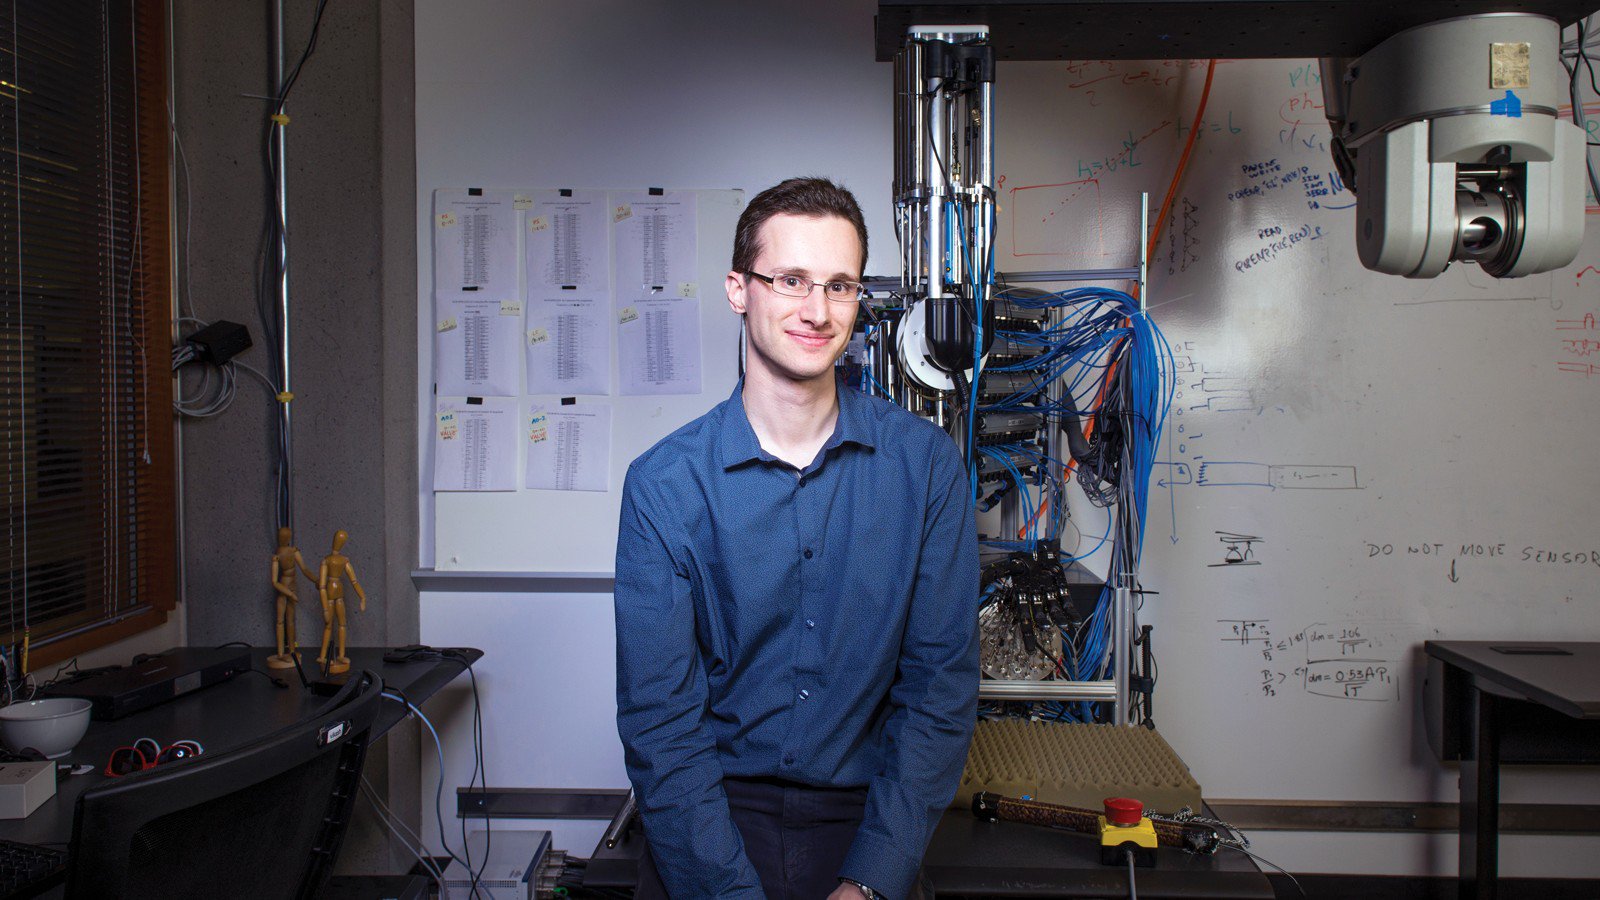
An early line of work joined what the robot saw to what its motors did. In a 2015 paper with Chelsea Finn, Trevor Darrell and Pieter Abbeel, Levine explored policies trained end to end from images to motor commands. It sounds tidy in a paper title. In a lab, the camera must cope with a changed object, an uncertain grip and an arm that learns only by trying. Another project gathered many grasping attempts so a system could use visual feedback to correct itself as it reached. The wager was that experience, carefully collected, could replace at least some of the hand-written instructions that made robots brittle.
“They never picked up any of the pieces themselves.”Levine, joking about AlphaGo in 2016
The joke landed while AlphaGo was making headlines for defeating a human champion. Levine admired the feat. His complaint was wonderfully literal: winning a board game and handling the board are separate achievements. The first lives in a clean account of moves. The second begins with eyesight, friction, fingers and a piece that may slip. His research was aimed at that stubborn second half.
Practice, and what practice misses
Levine tried several ways to make machines improve. He has described starting with a blank slate: let a robot practice one skill until it gets better. The difficulty is transfer. Shift the table or change the task, and the successful routine may become an expensive special case. At Google, where he worked as a research scientist, he also investigated collective learning with many robots gathering experience together. More practice helped, but a room of machines repeating one kind of work still did not know the rest of the world.
That tension has shaped the rest of his career. A robot needs broad prior knowledge to make sense of new instructions and unfamiliar scenes. It also needs the chance to practice a particular physical act until it becomes reliable. Levine sees a research problem in joining those strengths. Language and image models bring one kind of general knowledge; reinforcement learning brings the possibility of improving through the consequences of action. He has been candid that the combination is unfinished.
At Berkeley, he became a professor in 2016 and built the Robotic Artificial Intelligence and Learning lab around these questions. His courses on deep reinforcement learning circulate far beyond campus. Awards followed, including a 2017 NSF CAREER award, a 2019 Sloan fellowship and a Presidential Early Career Award. They mark a research program pursued through successive generations of algorithms. The enduring question is easy enough for a child to ask: if a machine did something once, why can't it do it better the next time?
The loop Levine wants to scale
A company built around the next attempt
Physical Intelligence was founded in 2024 by a team that includes Levine, Karol Hausman, Chelsea Finn, Brian Ichter, Lachy Groom, Adnan Esmail and Quan Vuong. The company wants to build models that can control different kinds of robots across many tasks. Its first generalist policy, π0, was introduced that October. It combined images, words and robot actions in a shared model and drew on data from multiple robots. The idea was to give a new task a useful starting point before the first local practice run.
The phrase “general-purpose” can make a technology sound finished long before it is. Levine's own accounts are more interesting because they keep the unfinished work in view. He has talked about a $400,000 robot used early in his robotics career and much cheaper arms available now. Lower hardware costs change the arithmetic of data collection. More robots can do more work, produce more examples and expose more errors. Still, a cheaper arm must learn to deal with an actual object in an actual place. A mountain has become easier to approach; nobody has abolished gravity.
His 2025 essay “Sporks of AGI” makes the data argument with a kitchen utensil. Simulation, human video and devices held by people can all teach useful things. Each is a substitute for a robot encountering the world with its own body. Levine's point is that a model eventually has to learn from the situation in which it will operate. His metaphor is funny because it is mildly unfair to the spork, which is useful right up until dinner gets complicated. In robotics, dinner gets complicated almost immediately.
“What we want to do is we want to put our robots in that zone of proximal development.”Levine on choosing tasks a robot can learn from
That phrase, borrowed from educational psychology, helps explain the coffee and the chocolate boxes. The first work a robot takes on must be within reach, yet difficult enough to reveal something it has not mastered. A box assembled all day is a source of repeated physical evidence. Coffee service brings a line of orders, cups, machines and small interruptions. These trials are useful because the work continues. A polished demonstration is an answer to a narrow question; a shift on the job asks another question every few minutes.
Physical Intelligence's 2026 work has continued to widen the experiment. The company described a reusable “physical intelligence layer” for robot builders, then published work on models with memory, faster online learning and π0.7, a model evaluated across several robot platforms and tasks. Those releases are research steps, not proof that a robot can walk into any room and start earning a wage. They show the shape of the effort: transfer what can be shared, practice what must be learned locally, and find out which failures teach the most.
BS and MS in computer science at Stanford; early work on body language and animated movement.
Stanford PhD completed; joins Pieter Abbeel's Berkeley robot learning lab.
Joins the Berkeley faculty and receives recognition for robots learning from their own attempts.
Co-founds Physical Intelligence; π0 brings a generalist approach to robot control.
Company experiments extend from office coffee to chocolate-box assembly and newer model releases.
The camera stops. The work starts.
Levine is unusually direct about the limits of a viral robot clip. He has observed that public demos often show a capability at its edge. They rarely reveal how often it works, what was rehearsed or what happens when the object changes. His preferred evidence is less photogenic: repeated attempts, papers that explain the setup, and conversations with the people who know where the system fails. This is the temperament of someone who has spent years watching robot arms miss by an inch.
He also resists the idea that real-world data collection is an impossible mystery. In a 2026 interview, he described it as industrial work: buy robots, train people, set up a process and keep it running. A laboratory may find that effort awkward or costly. A factory knows that physical work has always required equipment and routines. It is a bracingly mundane argument from a scientist trying to build something ambitious.
There is a pleasing loop in Levine's own route. He began by studying how to make motion look right in a virtual world. Then he moved to machines that had to make motion work in a real one. Now the research returns to learning at scale, asking whether an experience from one robot can help another and whether a shared model can keep improving as machines do useful jobs. The ambition is large. The test can fit on a desk: a cup, a box, a small surprise, another try.
The robot across the street will have to assemble the next chocolate box. That is the point. Sergey Levine is interested in what it carries from the last one.
Follow the work
Research, writing, conversations and video