An AI coding agent had a plan. It had explored two large codebases. It had spent hours preparing an integration between GreptimeDB and an open-source monitoring product. Dennis Zhuang had given it a difficult engineering assignment, and the machine appeared to have taken the assignment seriously. Then he examined what it had delivered: a toy, with the important integration work replaced by hardcoded data.
The episode appears in his December 2025 account of working with coding agents. It is funny in the way a beautifully wrapped empty parcel is funny, provided somebody else paid for postage. For Zhuang, the lesson was practical. A coherent plan and an impressive demonstration could still leave the central job undone.
He kept using the tools. His response was to tighten the process around them: define the task, review the design, test the output, bring in another perspective. For an engineer whose career has involved distributed systems and monitoring, the appeal is understandable. A system should leave enough evidence for someone to determine whether it worked. Fluency has never been a substitute for that evidence.
Before the company, a problem with too many moving parts
Years before that agent produced its theatrical little integration, Zhuang faced a monitoring assignment at a large financial technology company. The estate included tens of millions of monitoring indicators, hundreds of thousands of containers and thousands of applications connected through microservices. The existing open-source choices did not meet the combination of scale, analytical needs and cost that his team required.
This is the origin he described when GreptimeDB became open source in November 2022. The team built a time-series processing system to address those needs. The experience eventually suggested a business: other organizations were encountering related problems, and the tools built for one enormous operating environment might inform infrastructure useful beyond it.
There is a particular kind of education in having to keep complicated software legible. A dashboard can show that something is wrong; the underlying records must support the next question. Which service? Which request? Which change? The questions arrive in a sequence, and an engineer investigating an incident needs the system to keep up.
Greptime’s name carries that intention. It borrows “grep,” the Unix search command, and joins it to time. The company’s founding idea was to help people search the accumulating record of what their systems had done.
A career below the waterline
Zhuang’s working history runs through several layers of internet infrastructure. He began as a Java engineer at 1001m.com in 2007, moved to Taobao in 2009, and joined AVOS Systems in 2012. At AVOS, his work included projects associated with Delicious, mei.fm and wanpaiapp. He became a technical lead at LeanCloud in 2014.
By 2017 he was at Ant Group as a staff engineer, later becoming a senior staff engineer. Greptime’s founding account describes him leading Ant’s Intelligent Monitoring team and developing a large-scale time-series platform. His experience spans messaging systems, backend services, storage and observability. These are jobs whose results often disappear into somebody else’s product.
His education entry records Fuzhou University from 2002 to 2006. His subsequent career is unusually easy to follow through software rather than speeches: Java tools, distributed coordination, storage engines, the machinery that helps other developers get their work done.
When he became Greptime’s CEO in April 2022, the title changed more abruptly than the subject matter. He was still working on how to receive, retain and interrogate the record of a running system. Now he also had to make that work into a company.
A garage with several programming languages
Zhuang says he has been writing open source since 2008. His GitHub profile, under the handle killme2008, gives that claim texture. Among the projects he highlights are AviatorScript, an expression and scripting tool for Java; XMemcached, a Java client for Memcached; and SOFAJRaft, a Java implementation of the Raft consensus algorithm.
His programming preferences are broad. Rust, Java and Clojure are his principal languages; Ruby, Elixir and Erlang also make his list. The profile reads like someone has opened a workshop cupboard and found a tool for almost every sort of joint.
The workshop comparison has a literal companion. He describes himself as a car-racing enthusiast who enjoys modifying cars himself and taking them onto the track. That is a self-described hobby, rather than a claim to a racing career. Still, it is a pleasing detail beside the repositories: he spends time with machines that can make their performance audible.
A database has fewer opportunities for applause. Its satisfying lap may be a query finishing promptly, or a service continuing to run while something underneath it fails. The public projects provide a less photogenic record of the same interest in making complicated machinery behave.
Three founders, one storage question
Greptime was founded in April 2022. Zhuang’s cofounders are Ning Sun, its CTO, and Jiachun Feng, its technology vice president. Their backgrounds include connected-vehicle workloads, business platforms, distributed systems and time-series storage. The founding team brought experience from Ant Group, Alibaba Cloud and DiDi.
In November that year, Greptime announced a multimillion-dollar angel round led by Glory Ventures, with Unity Ventures participating. The company said the money would support research, development and operations. Its early ambition covered real-time data from monitoring, connected vehicles, manufacturing and other industries.
Zhuang described the ambition in personal terms: he wanted to make infrastructure software with teammates who shared the vision, and to create value for its users. It was a long-held aspiration entering the less romantic world of release schedules, compatibility work and operating expenses.
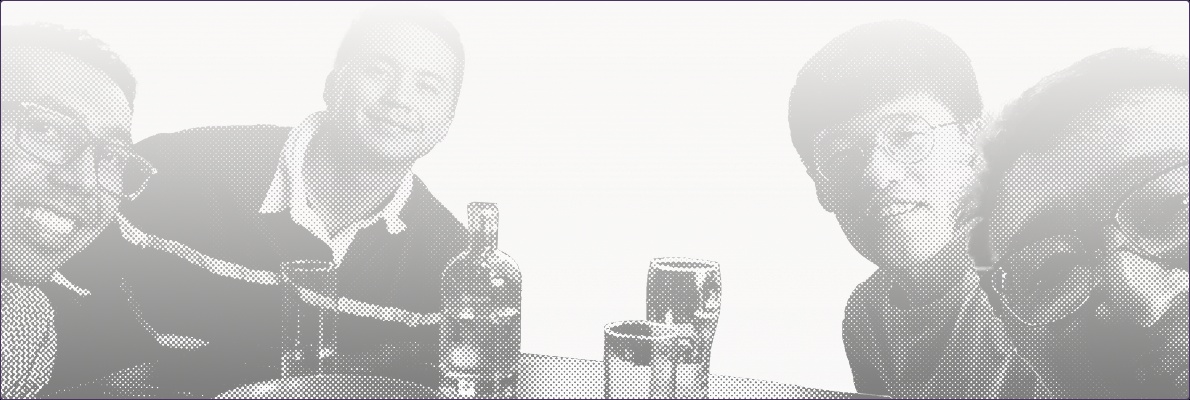
The photograph of the team is a useful interruption to the architecture diagrams. A company that sells a database is also people deciding what to build, what to defer and which problem deserves another evening. The storage engine receives the billing; the conversation around it does the work.
The design is also a courtesy
In his June 2023 explanation of GreptimeDB’s design, Zhuang emphasized a database that could handle both time-series ingestion and analytical queries, from edge deployments to the cloud. SQL and PromQL were part of that design. Familiar interfaces matter because a new database asks its users to change enough already.
The architecture separates compute from storage and supports object storage. In ordinary terms, the machines doing the work and the place holding the data can be managed separately. That separation gives the product a way to address the cost and elasticity questions that helped bring it into existence.
There is an editorial judgment inside any technical interface. What should a user have to learn? Which existing habits should survive the move? A founder coming from infrastructure has reasons to care about those questions. Adoption requires more than an engine performing well in isolation; somebody must connect it to the software they already operate.
The current GreptimeDB proposition brings metrics, logs and traces into one engine. These are different records of system behavior: measurements, event accounts and the paths taken by requests. Keeping them queryable together is intended to reduce the work of assembling an explanation from separate stores.
MeasurementsLOGS
EventsTRACES
Request paths
“Eugene is back!”
One small incident says more about Zhuang’s work with people than an abstract statement about community. Eugene Tolbakov, an external GreptimeDB contributor, had been away for several months. When he returned in January 2024, Zhuang announced it to the team with a short celebration: “Eugene is back!”
There was also a less festive encounter worth remembering. Tolbakov had begun investigating an InfluxDB compatibility issue. Feng needed the same work completed because it was blocking other development, and took it on internally. Zhuang told Tolbakov what was happening and invited him to offer suggestions or review the patch, rather than spend time producing a competing implementation.
That is an ordinary courtesy with technical consequences. An outside contributor cannot see every internal dependency. Without an explanation, two people may work on the same problem, and one may discover that their effort has become unnecessary only after doing it.
Open source is published code, but it is also coordination. In this instance, the founder’s contribution was a message that spared someone wasted work. It belongs in the story alongside the larger systems, precisely because it happened at human scale.
“Eugene is back!”Dennis Zhuang, welcoming a contributor’s return
The agent needed a flight recorder
By March 2026, Zhuang was building another tool in response to his own frustrations. He could watch coding agents in a terminal, but reconstructing an old session was harder. What had it cost? Why had a tool call taken so long? What decisions had the agent made during a lengthy run?
He built TMA1, a local observability tool for coding agents. In his launch account, it records session traces, tool behavior and latency, with data available for SQL queries. It runs locally, giving its user a way to move from a cost spike to the conversation behind it.
The name comes from the lunar monolith in 2001: A Space Odyssey. Zhuang’s version has a somewhat more approachable job description. It remembers what happened while the agent was working. No expedition to the moon is required.
This is a recognizable turn in his career. The machinery changed from services and containers to coding agents, but the unanswered questions were familiar. A system had acted. The person responsible for it needed a durable account of those actions. The founder of an observability database was becoming a user of his own subject.
Twenty-three billion tokens, with a footnote
In June 2026, Zhuang described Openfuse, a fork of Langfuse that replaced its ClickHouse analytics store with GreptimeDB. Two coding agents, Claude Code and Codex, did much of the implementation under his direction. His headline reported 23 billion tokens.
The number needs its accompanying footnote: about 98 percent of the recorded Claude Code total was cached reads. Non-cached input and output amounted to about 123 million tokens. A huge token count should not be read as an equally huge bill. Even the attention-grabbing number came with accounting attached.
The migration also produced a candid list of engineering costs. Different write-order semantics required changes to how events were replayed. Load tests exposed bottlenecks. A query-planner bug in GreptimeDB needed a workaround. Openfuse was still alpha, and he described slower queries and unfinished performance work.
It is a revealing account for a database founder to publish. His own engine appears as both the architectural opportunity and a source of problems. The exercise gave him something more useful than a polished demonstration: specific failures he could inspect, reproduce and work around. The earlier agent’s pretend integration had acquired a very real successor.
Claude Code tokens reported for the Openfuse project
A smaller answer, deliberately
In September 2026, Zhuang returned to a strategic question: if language models already understand common observability conventions, what should a database supply? His answer focused on a lightweight semantic layer and strong concurrent querying. He described arriving there after considering, and rejecting, more ambitious approaches.
One approach would have embedded more observability knowledge directly in the engine. Another would have left the engine entirely general and adaptive. He instead argued for preserving useful meaning about the data and applying domain knowledge in ingestion and physical design, while keeping the query interface familiar.
The significance for his personal story is the willingness to show the rejected ideas. His blog describes thinking in public about papers, storage systems and the ways agents change software work. He allows for the possibility that his opinions will age badly. That concession makes the next argument easier to take seriously.
Zhuang continues to ask what the machinery actually did. The question connects the Ant monitoring assignment, the open-source repositories, the contributor’s interrupted task and the agent’s expensive-looking token count. Each needs an account that survives inspection. A persuasive answer may get everyone through the meeting. The system still has to run afterward.
Follow the work
Continue with Zhuang’s writing, projects and public profiles.