The bank had reached its verdict before the experiment could begin. Anand Kannappan’s brother worked at Piper Sandler, which had blocked access to OpenAI. To Kannappan, the restriction exposed a gap between what generative AI could promise and what a business would permit. A chatbot might produce a remarkable answer. Someone still had to accept responsibility for the unremarkable answer that happened to be wrong.
That was a useful problem for a founder to notice. Plenty of people were asking what they could build with language models. Kannappan and Rebecca Qian were interested in how anyone would know whether the thing they had built worked. The question sounds almost impolitely basic beside a dazzling demonstration. It becomes rather more welcome when the demonstration is about to become somebody’s job.
In 2023, they founded Patronus AI. Kannappan became CEO; Qian became CTO. By June 2026, the company had announced $70 million across three funding rounds. Its work had expanded from evaluating model answers to designing simulated digital environments for agents. The scale had changed. The troublesome question had survived.
A restriction becomes a reason to build
Kannappan and Qian had met while studying computer science at the University of Chicago. They later worked at Meta, where their interests approached the same machinery from different directions. Qian worked on responsible natural language processing research. Kannappan developed explainable machine learning frameworks at Reality Labs. Understanding an output, rather than simply obtaining one, was already part of their professional lives.
Before Patronus, Kannappan had also co-founded Kyber Technologies. The business used AI and remote sensing data to predict market events and evolved into a quantitative futures hedge fund. He has described running a fund backed by Mark Cuban and Howard Morgan. His experience also includes Vertis. It is a career with repeated encounters between mathematical models and decisions made outside a laboratory.
The new venture initially had to explain its vocabulary as well as its product. Kannappan later recalled debating with Qian whether to use the word “evaluation” in their messaging. It sounded like a research activity. Would anyone else know what they meant? A company selling tests had encountered its first test: explaining why the exam should exist.
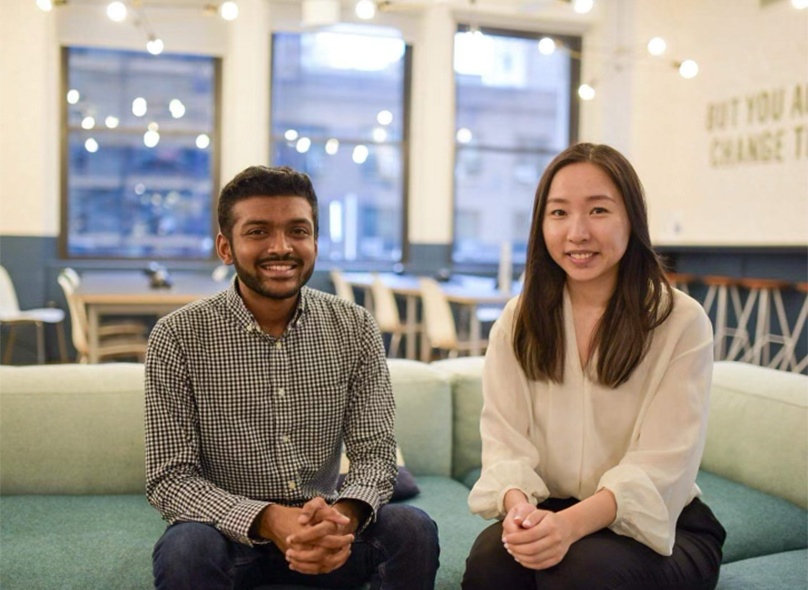
Patronus launched from stealth in September 2023 with a $3 million seed round led by Lightspeed Venture Partners. The premise was concrete enough: companies needed to find model mistakes repeatedly, across many examples, without turning every release into an exhausting hand-marking exercise. The founders were proposing a way to make scrutiny part of the machinery.
The price of a plausible answer
FinanceBench gave that premise a particularly exacting setting. Kannappan was among the authors of the November 2023 paper, alongside researchers including Qian, Pranab Islam and Douwe Kiela. The benchmark asks questions grounded in public financial documents, with answers and supporting evidence. A confident paragraph has to meet the filing.
The researchers examined 16 model configurations on a sample of 150 cases and manually reviewed 2,400 answers. In one retrieval-based GPT-4-Turbo configuration, the model answered incorrectly or refused to answer 81 percent of the questions. The figure belongs to that setup and sample. It is not a permanent score for every model, or a description of every financial task.
Incorrect answers or refusals for one GPT-4-Turbo retrieval configuration on 150 questions.
A result from a particular experiment, not a universal failure rate.Its force came from the specificity. Give a model access to material and it may still fail to use that material correctly. Retrieval supplies evidence; it does not automatically confer judgment. Anyone who has watched a meeting proceed despite a very informative spreadsheet will recognise the distinction.
For Kannappan, this made evaluation a practical adoption problem. In the company’s early work, enterprises could compare models, generate demanding test cases and score outputs against criteria relevant to their own applications. A useful test needed to resemble the work being attempted. Passing a general exam would offer limited comfort to a team whose product failed on the one question its customers actually asked.
The financial setting also made the stakes legible without requiring a lecture about neural networks. An answer could be grammatical, courteous and entirely unsuitable for use. The surface qualities that make a chatbot pleasant to talk to provide a rather poor substitute for checking its arithmetic.
Who grades the grader?
Checking everything by hand creates its own bottleneck. Patronus’s response included models designed to evaluate other models. Kannappan co-authored the July 2024 Lynx paper, which examined a stubborn problem in retrieval-based systems: an answer may contain claims unsupported by, or contradictory to, the context supplied to it.
Lynx was released with an evaluation benchmark and code. The approach made the judge available for inspection and further research. That matters because putting another model in charge of marking does not remove uncertainty. It creates a second set of decisions to understand. An examiner can be fluent too.
GLIDER, a paper published that December with Kannappan among its authors, widened the idea. Its three-billion-parameter evaluator could score text and context against user-defined criteria, provide fine-grained feedback and highlight relevant spans. The research described training across 685 domains and 183 criteria. Those details show the effort involved in teaching a model what “good” is supposed to mean across different settings.
There is a recognisable preference running through this work: a grade becomes more useful when a person can inspect the reason behind it. A single number is easy to display. The difficult part is making that number answerable to examples, criteria and human judgment.
Kannappan has also publicly tied research to product impact. After hosting more than 100 researchers and engineers at Patronus, he described wanting to balance research with product, and argued that customers give applied work a way to demonstrate its value. His version of a research agenda has room for papers, but also for the engineering needed to turn an idea into something another person can use.
Following the first wrong turn
Agents made the exam longer. A chatbot can be judged on a response. An agent may search, call tools, edit files and revise a plan before it delivers anything. A mistake near the beginning can travel quietly through the rest of the workflow. By the time the final answer arrives, the interesting event may be several pages back.
TRAIL, published in 2025 and co-authored by Kannappan, addressed that history. It introduced a taxonomy of agent errors and 148 human-annotated traces from tasks including software engineering and information retrieval. The research asked models to locate failures in the route, rather than merely react to the destination.
The results were demanding even for the evaluators. The paper reported that its best-performing model, Gemini-2.5-pro, scored 11 percent on the benchmark. That is a result about trace debugging in this experiment, rather than an overall intelligence rating. Finding an error in another system’s chain of decisions is a separate skill from producing a plausible answer yourself.
The personal continuity is striking. At Meta, Kannappan worked on interpreting machine learning. At Patronus, the object requiring interpretation had acquired tools and a longer itinerary. The demand for an explanation had followed it out of the model and into the workflow.
A world to practise in
In May 2024, Patronus announced a $17 million Series A led by Notable Capital. Two years later came a $50 million Series B led by Greenfield Partners, alongside a preview of a Digital World Model. The funding rounds mark the company’s growth; the accompanying research describes the direction Kannappan wants it to take.
The idea is to simulate digital environments that respond to an agent’s actions. A model operating inside software needs more than facts about that software. It needs experience of actions, consequences, rules and unexpected states. A practice environment can let it attempt a task, observe what happens and try again.
Patronus draws an analogy with autonomous driving, where simulation helps explore situations that would be difficult to encounter repeatedly on actual roads. Digital workflows introduce their own variety: code, research, communication and many combinations of tools. The ambition is to create training experience at a scale that hand-built tasks struggle to supply.
The preview is a statement of direction, rather than proof that every simulated lesson will transfer to real work. That transfer is the interesting test. A practice world must preserve enough of the real world’s awkwardness to teach something useful. Otherwise an agent can become impressively accomplished at a very accommodating game.
FigmaTrace, released in August 2026 with Kannappan among its authors, offers a complementary route into that problem. Its 3,469 trajectories preserve more than 200 hours of human design work across ten skills. The sequence matters: a finished screen hides the choices, corrections and interactions that produced it. Capturing those steps makes expertise available as a process to study.
Achilles gets another assignment
Then there are the actual games. September’s SpeedrunBench tests agents on ten titles and measures how many frames they need to reach a goal. It can ask an agent to act on the current frame, improve a complete action sequence or construct one from scratch. Completion leaves another question waiting: could the route be better?
That is an unusually apt expression of Kannappan’s outlook. He has revealed that Patronus originally operated in stealth as Zeno AI. The name referred to the ancient paradox of Achilles pursuing a tortoise. In his retelling, every improvement in AI gives people better tools for defining the next challenge.
“Every finish line we draw for AI moves”Anand Kannappan, September 2026
He is optimistic about where that pursuit leads. His ambition is scalable oversight: ways of understanding and guiding increasingly capable systems without requiring a person to inspect every move. It is a large aspiration built from rather particular questions about documents, traces, design tools and game frames.
There is a smaller literary detail too. Asked for his favourite books on a podcast, Kannappan chose the Harry Potter series. The founder who eventually helped build Patronus had first named his company after a Greek philosopher. Apparently the reading list could accommodate both a wand and an unresolved problem.
The unresolved problem is useful company. Better models make harder tasks possible; harder tasks demand better checks. Kannappan has placed his working life inside that exchange. The next passing grade will be welcome. Then someone will have to write the next question.
Keep following the questions
Writing, research and conversations with Anand Kannappan.
- Personal site
- X / Twitter
- GitHub
- Google Scholar
- Hugging Face
- Patronus AI
- Zeno’s Paradox in AI
- The founding interview
- FinanceBench paper
- Lynx paper
- GLIDER paper
- TRAIL paper
- FigmaTrace research
- SpeedrunBench research
- Watch: NYSE conversation
- Listen: Infinite Curiosity
- Watch / listen: Venture with Grace
- YouTube: Enterprise AI Show channel