Imagine a bank’s voice assistant asking whether you recognize a charge. You say yes. Now imagine saying the same word slowly, with a wobble of uncertainty. On a transcript, the answers are twins. To a human listener, they might require entirely different next questions. Hume AI uses this example to explain the problem it has chosen to pursue: the words can arrive intact while the meaning gets damaged in transit.
- Hume turns emotion research into expressive speech and tools for evaluating voice AI.
- Octave makes voices; EVI puts them into live conversations.
- Its 2026 strategy emphasizes the data and human judgments other builders need.
The interesting part is what happened next. Hume made software that could speak expressively. Then it began selling the infrastructure for determining whether somebody else’s software was doing the job properly. In a market filled with voices auditioning for our attention, there is a business in being the person who listens.
The meaning hiding between the words
Founder Alan Cowen came to the question through emotion science. His research uses computational methods to map expression across voice, face, and other behavior. Hume’s scientific approach concerns distinctions finer than the familiar handful of emotions: how people express themselves, how others perceive those expressions, and how the distinctions can be represented in data.
There is a charming historical ambition behind the name. The company invokes David Hume, the philosopher who treated emotion as central to choice and well-being. The modern operation is rather more computational: annotated recordings, human studies, and models. Its declared mission is to make AI serve human goals and emotional well-being. The question is how to turn that sentiment into something an engineer can test.
From measuring emotion to making a voice
The commercial answer first took the form of expression-analysis tools. Developers could measure expressive signals in media instead of reducing every interaction to a positive-or-negative label. Hume subsequently moved into generating the other side of the conversation. In March 2024, it announced a $50 million Series B led by EQT Ventures alongside its Empathic Voice Interface, or EVI.
EVI handles voice interaction, including interruptions and deciding when a speaker has finished. Octave, its text-to-speech offering, lets developers generate expressive audio, design voices, and give acting instructions in ordinary language. A creator can ask for a whisper; a product team can seek an authoritative but approachable delivery. These are usable controls over a performance, rather than a promise that a machine possesses feelings.
Octave 2’s launch preview expanded multilingual speech generation. Hume reported audio generation under 200ms; that figure is not a guarantee of total application response time.
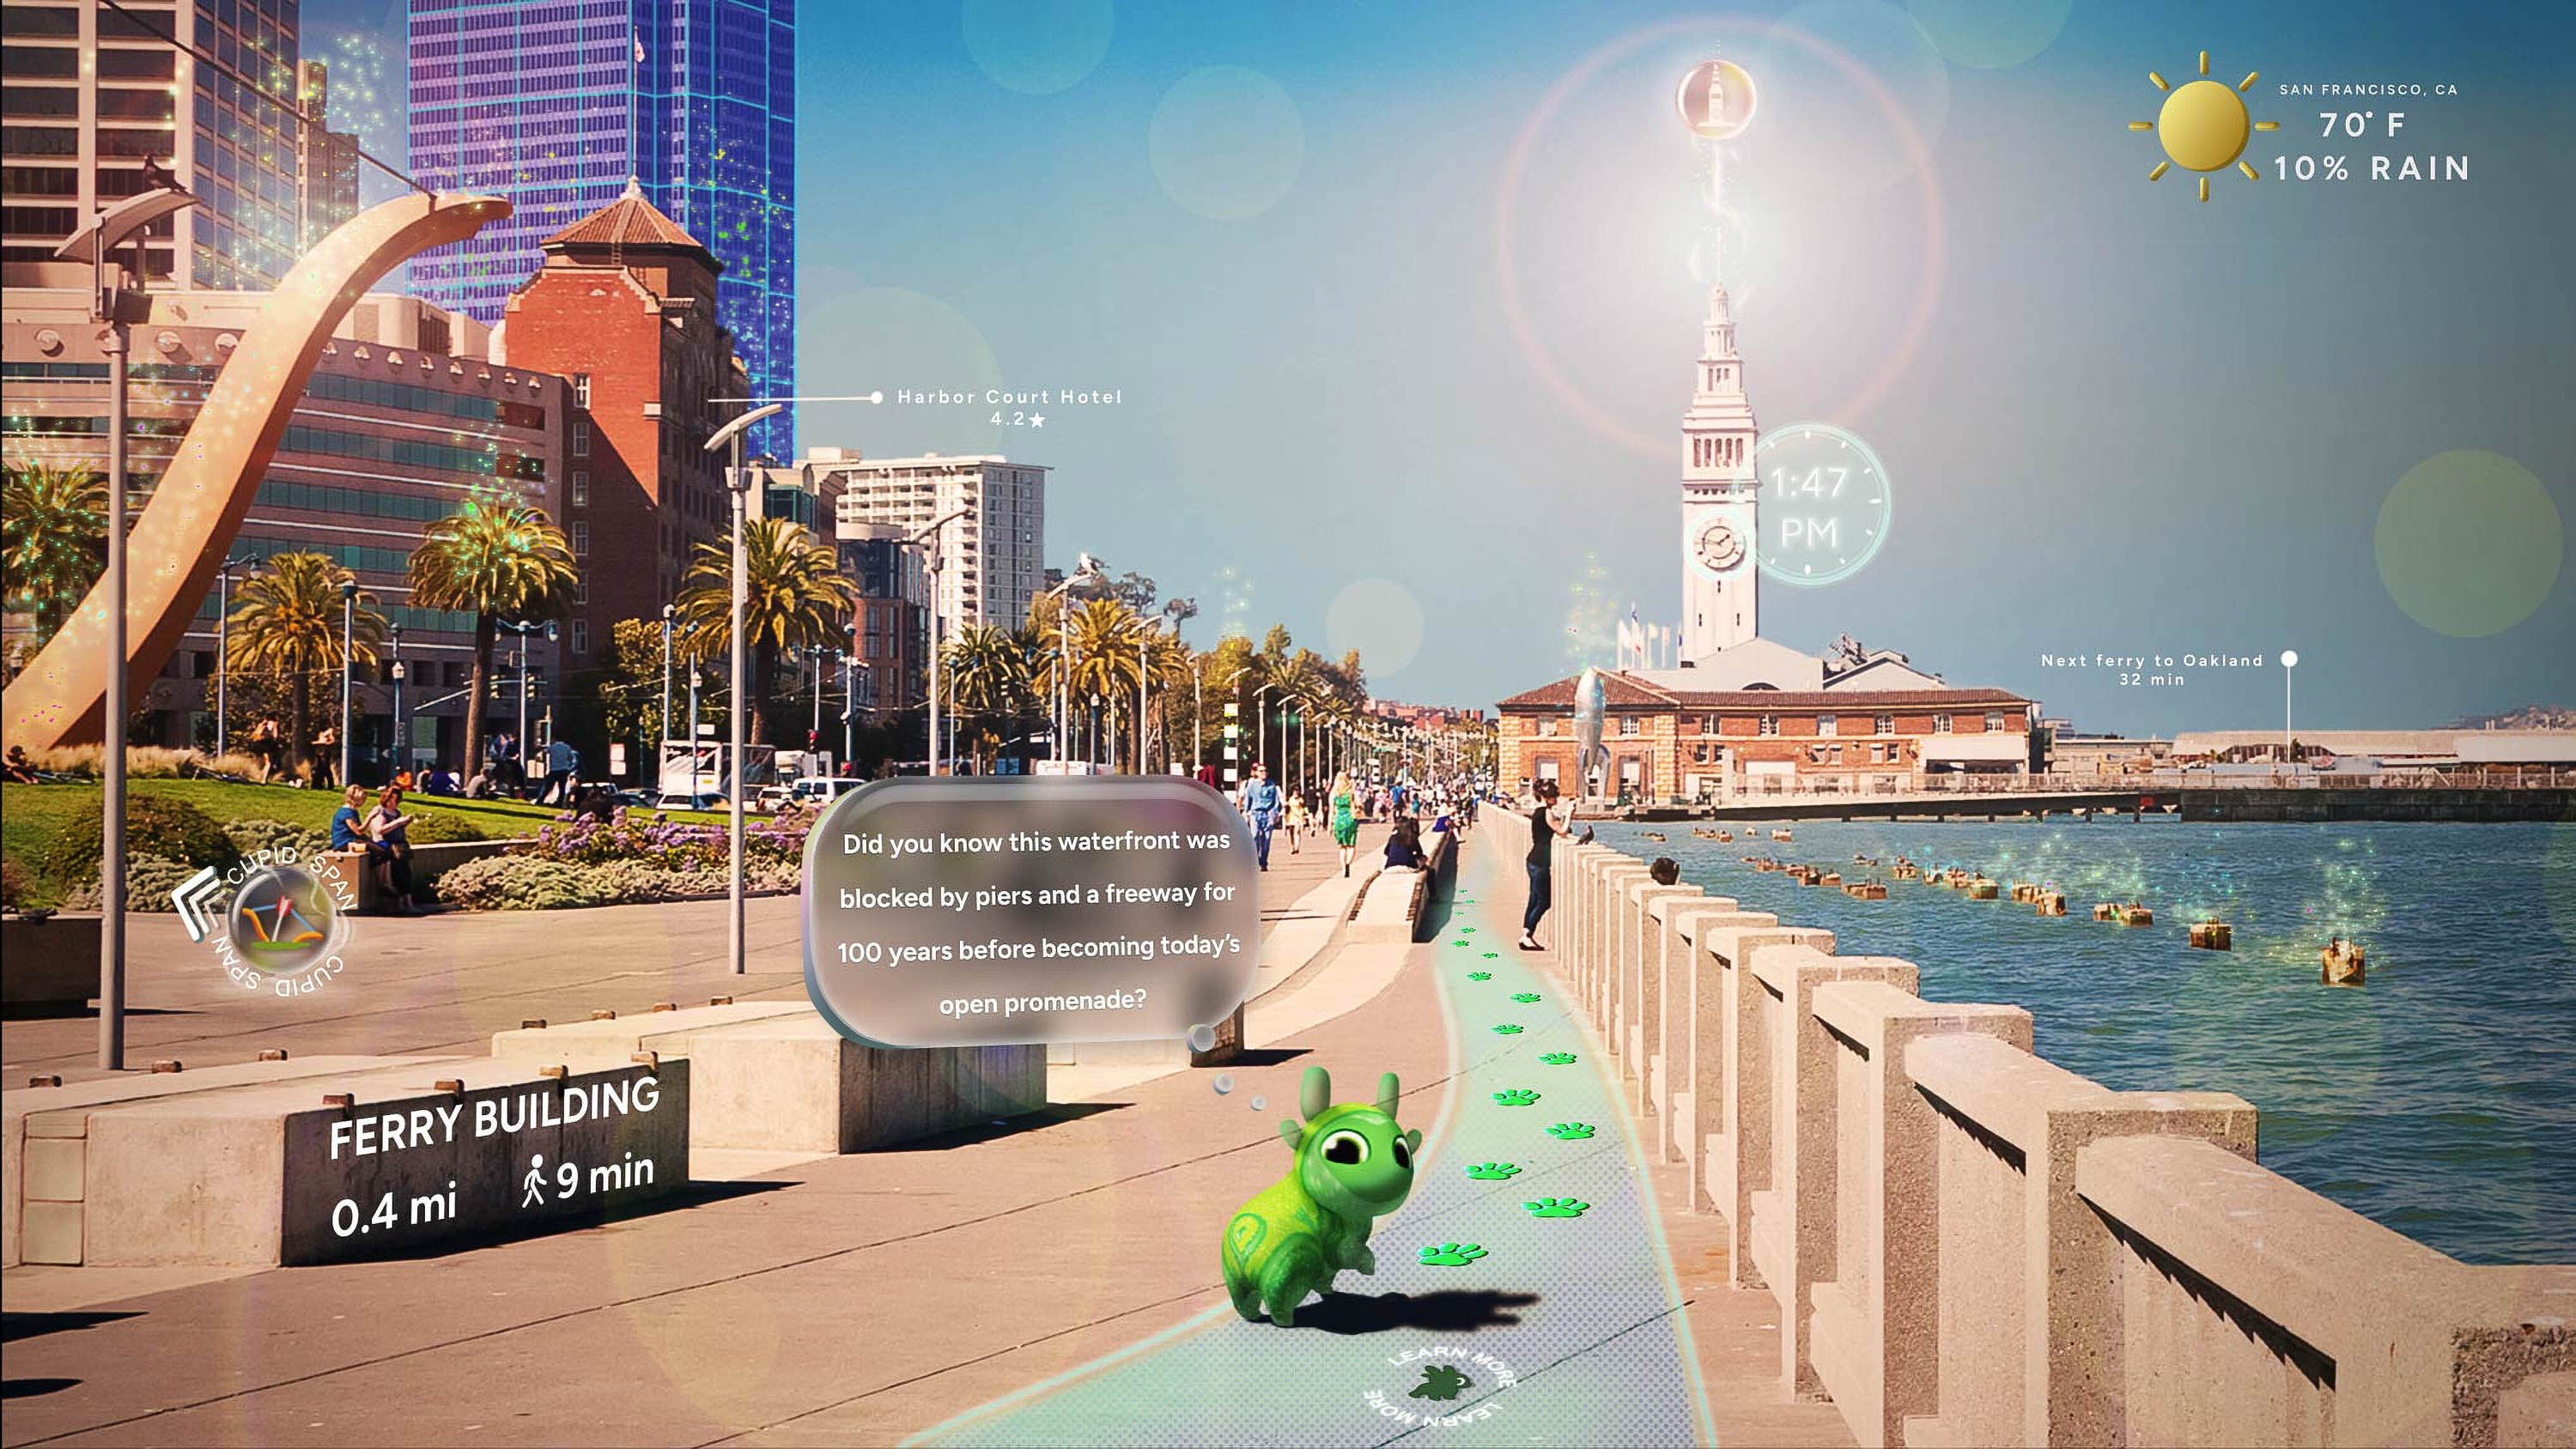
The uses are pleasingly varied. Roofing manufacturer GAF uses Hume’s speech technology for training videos and marketing voiceovers. Niantic Spatial combines EVI with geospatial intelligence and Snap Spectacles in Project Jade, whose companion Dot speaks to users exploring the physical world. One customer needs an instructional voice; another needs a guide that can talk about what the wearer sees.
Hume’s business model supports both experimentation and volume: subscriptions, included voice usage, and overage charges. Its public Pro plan lists $70 a month. Managed external language models add costs, and research engagements go through sales. The practical calculation therefore includes the speech service, the reasoning system, and the amount of testing needed before customers encounter either.
Then Hume started selling the test
January 2026 brought a revealing change. Hume appointed Andrew Ettinger CEO, announced a non-exclusive technology license to Google, and said Cowen had joined Google. The company announcement described an expanding research infrastructure business. The disclosed arrangement was a license and founder move; calling it a purchase of Hume would tell a different story.
“Voice in AI is evolving from a feature to the primary interface for the next generation of applications and devices.”
Andrew Ettinger · January 2026
Ettinger’s subsequent argument is economic. As natural-sounding models become more common, their differences become harder to hear in a short demonstration. Buyers still need to know which system survives their callers’ accents, frustration, interruptions, and complicated requests. Hume’s bet is that those questions create demand for measurement, even when the voice itself becomes cheaper.
An API call with people on the other end
The current offering makes that bet concrete. Data Solutions licenses recordings and supports custom collection. Expression Measurement provides offline tagging and live prosody analysis. Kairos generates scenarios, runs simulated or human conversations, and checks regressions between versions. The Human Feedback API recruits participants to rate clips, compare samples, or talk with a model, returning structured judgments to the development workflow.
- 01 Collect the right data
- 02 Run the hard conversation
- 03 Ask human listeners
- 04 Improve. Test again.
Task success and emotional appropriateness need separate checks.
This is where Hume’s position differs from simply choosing ElevenLabs, Cartesia, or another voice generator. It wants to help evaluate models from other suppliers, using infrastructure developed alongside its own speech research. Its July 2026 Real World VoiceEQ paper argues for multiple dimensions of performance: a natural voice can be unreliable, and access to audio does not ensure a system uses emotional cues.
Try the difficult conversation first
The weakness Hume identifies begins early in a conventional pipeline, when transcription discards tone. Native audio systems preserve more information but introduce their own trouble: voices can drift, personas can become inconsistent, and interruptions can go badly. Hume’s June 2026 assessment acknowledges those production uncertainties. The architecture is a hypothesis to test, rather than permission to skip testing.
A builder can copy the discipline: compare models on the same difficult scenarios, conceal model identities from human raters, and rerun evaluations after releases. Choose participants and conditions that resemble the actual audience. Scores describe observable expression and perceived quality; they cannot certify someone’s private feelings. The useful purchase is evidence that a voice handles your particular conversation. A fine audition is only the beginning.