A recommendation can look successful for a second. Someone clicks. A counter moves. Somewhere, a dashboard acquires a pleasing shade of green. But what happens next? Does the person return? Did the recommendation help? Was the machine learning anything useful, or merely collecting applause for the first move? Zheqing (Bill) Zhu has spent much of his research career asking questions that begin after the apparent ending.
His work with Stanford professor Benjamin Van Roy examined recommendations as a sequence of decisions, with feedback arriving late and sometimes sparingly. That is an awkward arrangement for anyone who prefers immediate confirmation. The system has to make a choice, observe what follows, and decide whether to repeat it. A click is evidence. It is also a very small slice of a life.
Today Zhu is founder and CEO of Pokee AI, based in Bellevue, Washington. He brings that interest in consequences to agents that use online tools. A generated answer can be inspected in one sitting. A workflow stretches across services, permissions, intermediate results, and opportunities to get the next step wrong. His chosen subject has followed him from recommendation systems into the working day.
“We want to solve the execution problem,” he said when Pokee announced its seed funding in July 2025. It is a compact ambition with an inconvenient amount of work inside it. Computers have been offering to make office life easier for decades. Office life has responded by opening another tab.
“We want to solve the execution problem.”
Bill Zhu · July 2025
Two jobs, one research question
Zhu graduated from Duke in 2017 and joined Meta, then Facebook, as a machine learning engineer in Ads Growth. He moved into engineering management and technical leadership in 2018, then led the Applied Reinforcement Learning team from 2021 to 2024. The progression put him increasingly close to the question that governs applied research: what survives contact with an operating system, a business, and actual users?
Alongside that work, he pursued graduate study at Stanford. He earned a computer science master's degree in 2020 and completed his doctoral research while working full time at Meta. Van Roy advised the PhD. It is an unusually direct connection between academic questions and production constraints: the systems being studied belonged to the same broad world as the systems being shipped.
The doctoral dissertation was titled Efficient Deep Reinforcement Learning for Recommender Systems. Even the title carries a useful restraint. Efficiency matters when a method leaves a research setting. A clever procedure that consumes more resources than an application can spare has a rather limited social calendar.
The 2023 paper Deep Exploration for Recommendation Systems, coauthored with Van Roy, investigated learning from delayed feedback. Its experiments used industrial-grade simulators. The point was to examine decisions over time, including choices that reveal information for later decisions. That requires looking beyond the immediate reward. Sometimes the useful move is the one that teaches the system something.
It is tempting to compress this period into a heroic tale of sleepless nights. The public record offers something more interesting: a sustained overlap between research and responsibility. Zhu kept studying the gap between theoretical algorithms and practical applications while managing people whose work had to cross it.
- 2017Duke graduate → Meta engineer
- 2020Stanford MS + full-time Meta work
- 2023Doctoral research completed · Pearl released
- 2024Pokee AI founded
- 2026Isaac model + enterprise security research
Pearl, with the machinery showing
In December 2023, the Applied Reinforcement Learning team released Pearl, an open-source library for building reinforcement learning agents. Zhu was a lead author of the paper describing it. The work later appeared in the Journal of Machine Learning Research. Pearl addressed difficulties that are easy to leave outside a tidy demonstration: incomplete information, changing sets of available actions, and the need to explore without making reckless choices.
Its modular design let developers combine capabilities for a particular application. Recommendation systems, auction bidding, and creative selection require different mixtures. A system placing bids may need to summarize history; another choosing creative material may need to handle a changing menu of actions. Pearl made those distinctions part of the design.
That detail gives Zhu's career a recognizable shape. He helped build a library intended to accommodate the messiness of deployment, then founded a company whose agents would have to navigate it. The continuity is more revealing than the change of business card.
Pearl also made the work available beyond Meta. Researchers and practitioners could inspect the code and assemble agents using its components. In his announcement, Zhu thanked a long list of colleagues. Yi Wan, a Pearl coauthor, later became Pokee's founding research scientist. The move into a startup carried an existing technical connection with it.
Zhu has also helped organize the conversation around deployment. He chaired the AAAI 2023 Reinforcement Learning Ready for Production workshop and advised a deployable reinforcement learning workshop in 2024. Those titles are almost a recurring editorial note attached to his career: please explain how this will work when people depend on it.
Four people in the snow
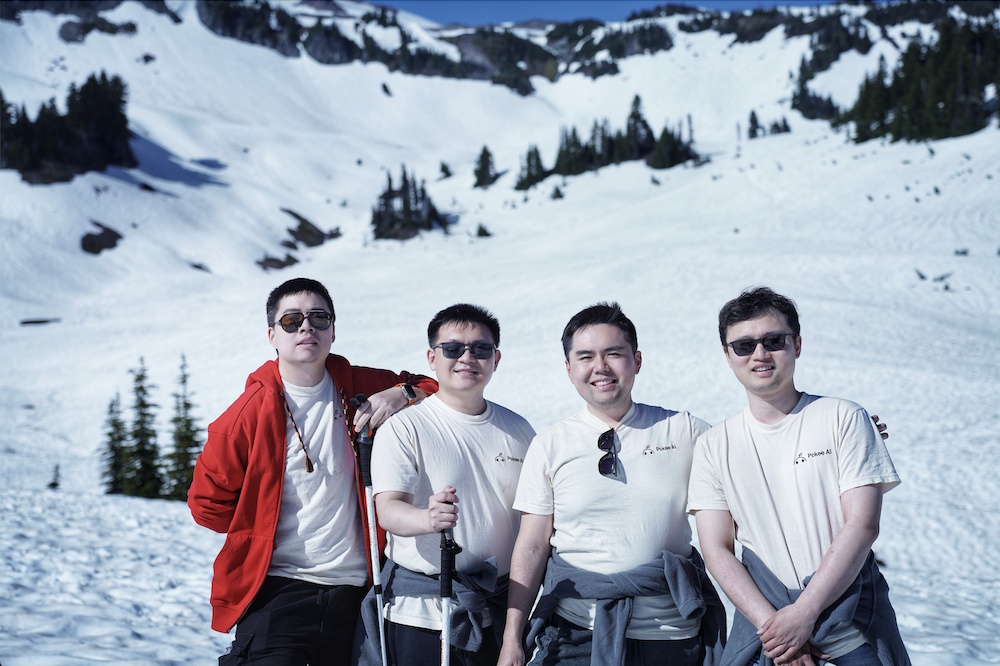
The founding-team photograph is a welcome interruption to the usual visual vocabulary of AI companies. There are mountains, snow, four people, and an entirely reasonable number of hiking poles. Zhu stands third from the left, smiling, sunglasses hanging from his shirt. Nobody appears to be pointing at a glowing diagram.
With him are Michael Cai, head of product engineering; Christopher Wu, head of machine learning engineering; and Yi Wan. Their roles suggest the practical breadth of the undertaking. Research needs an engineering home. The engineering needs a product someone can use. A founder then has to persuade people that the assembled thing is worth their time.
Pokee began in 2024. In July 2025 it announced a $12 million seed round led by Point72 Ventures, with Qualcomm and Samsung among the backers. Its public beta was live that month. These were early milestones, accompanied by a specific approach: use reinforcement learning to help agents choose tools and put their actions in a useful order.
Zhu's connection to the Seattle area predates the company. When he received the CIE-SEA Asian American Science and Engineering Innovation Award, he recalled a Microsoft internship as the beginning of his attachment to the city. He also described meeting his lead investors, Ryan Fauber and Sri Chandrasekar, there. Geography, in this version of the founder story, includes remembered people as well as an address.
Led by Point72 Ventures
The plan meets a broken tool
A user's request can sound almost offensively simple: prepare something, put it in the right place, and tell the right people. For an agent, each verb opens another set of decisions. Which tool should it call? What information does that tool need? Did the call work? Does the returned result actually allow the next action? The nice sentence at the beginning has turned into a small administrative expedition.
PokeeResearch-7B, described in an October 2025 paper coauthored by Zhu, brought those concerns into research tasks. The seven-billion-parameter agent gathered information through web tools and worked through cycles of research and verification. A failed tool call could trigger another attempt. A draft answer could be checked and sent back for further work.
Its training used feedback from an AI judge to assess answer correctness, alongside a smaller reward for following the required format. The design treated a response as something to evaluate, rather than an automatic stopping point. The authors reported results across ten benchmarks, comparing the model with other research agents of similar size.
The useful idea is legible without a benchmark table: finishing includes checking. Anyone who has sent a document and then noticed the wrong attachment understands the distinction. Here it became a research design, with mechanisms for retrying and verifying built into the agent's path through a task.
The team released model and inference code publicly. That gave other developers a way to examine the implementation, an extension of the open-source habit visible in Pearl. Zhu's public work continues to include coauthored research even as the business requires product decisions, funding, and partnerships.
A founder goes to Wall Street
In a public post about an interview at the New York Stock Exchange, Zhu offered a less technical observation. His first visit, he wrote, “felt like stepping into a Wall Street movie scene.” After years of recommendation algorithms and production libraries, there was still room for the straightforward novelty of walking into a famous room.
His enterprise argument has become more concrete, too. In a May 2026 interview, he emphasized agents that operate where a customer's data already lives, including private infrastructure and the customer's own hardware. Deployment location becomes part of the product. For an organization deciding what an agent may see and do, the machine's address matters.
By August 2026, Zhu was a coauthor of the technical report for Pokee-Isaac 28B. Pokee describes it as an agentic model with a ten-million-token context window and options for deployment inside a customer's infrastructure. That is the company's specification. Its practical proposition is that an agent can work with a large, connected body of material while remaining inside an organization's chosen boundary.
September brought another coauthored report, on enterprise agent and model security. It considered the wider execution stack: tools, retrieval, memory, external environments, and serving infrastructure. The concern fits the earlier career. Once software acts, its behavior depends on more than the model producing the next instruction.
Zhu's path now runs from investigating delayed rewards to selling systems intended to carry work through to completion. Each stage adds another obligation: choose, observe, verify, deploy, control. His ambition is large, but the daily test is small enough to recognize. A task arrives. A series of decisions follows. At the end, somebody needs the job to be finished.