In 2018, Vahan Petrosyan was studying a strangely literal problem: where, exactly, does one object in an image end and another begin? At a computer vision conference, he saw companies paying people to draw those boundaries. His research into image segmentation might make that labor faster. He and his brother Tigran left their PhD programs and began building SuperAnnotate. It was an origin story measured in pixels. The company they built now asks a less visible question: when a machine answers a person, who decides whether it got the answer right?
The short version
- SuperAnnotate sells software for preparing and evaluating AI data, alongside access to managed expert reviewers.
- Its customers include Databricks, Flo Health, ServiceNow, Wizard and Superhuman; their projects span benchmarks, health answers, shopping recommendations and writing tools.
- The business moved from precise image labels to multimodal training data, model evaluation and agent workflows.
- The transferable idea is simple: define “good” in a rubric, test it on a small set, and send ambiguous cases to people who can explain their judgment.
A polygon with ambitions
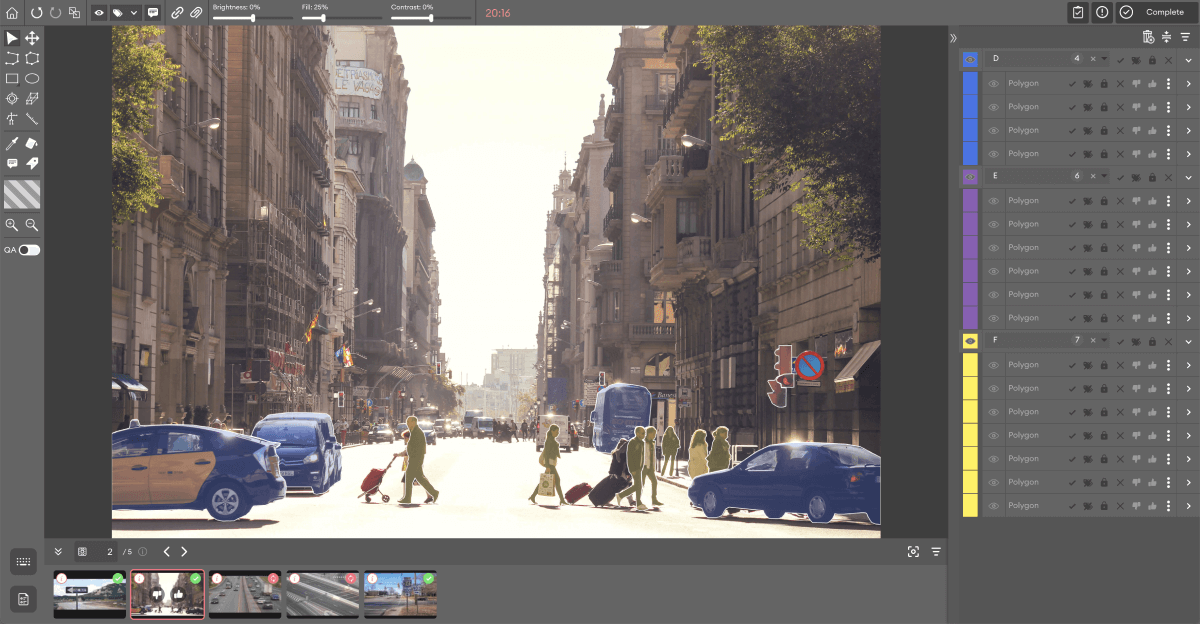
The first product made a narrow piece of computer vision work less painful. A person could outline an object, correct an automated suggestion, and send the result through review. That sounds like a drawing program until the job grows. Then somebody must assign thousands of images, keep instructions current, spot the reviewer who misunderstood them, and return usable data to the model team. The boundary is only the visible part of the process.
SuperAnnotate entered Berkeley SkyDeck in 2019, opened its image annotation platform to the public in 2020, and raised a $14.5 million Series A in 2021. Its early software handled polygons, boxes, keypoints, video and text. What the founders had found was a market for managing the work around the label: people, versions, quality and iteration. A machine learning team could build that plumbing itself. It could also spend months maintaining it.
The definition of “good” changed
Generative AI altered the work in 2023. An image of a car can be outlined. A chatbot answer may be accurate but evasive, helpful but unsafe, or plausible and entirely invented. Agents add another layer: the final answer might be fine while the steps used to reach it were reckless. The reviewer now needs a rubric, context and a record of the model’s path. A single thumbs-up is too blunt an instrument.
SuperAnnotate expanded into configurable interfaces for text, image, video and audio; preference data for fine-tuning; model evaluation; and, more recently, agent trajectories and reinforcement learning environments. Its platform routes items through human review, automated checks and models acting as judges. It also offers managed specialists when a client needs people who can read a clinical answer or parse a financial table. That combination is its pitch against a spreadsheet, an in-house tool, or a platform that stops at the label.
Consider Flo Health’s AskFlo assistant. Health questions cannot be judged by fluency alone. Flo needed medical experts to check more than 12,000 model outputs against clinical guidance and to keep evaluation moving as the product changed. In a published customer case study, the company said a pipeline built with SuperAnnotate and Databricks moved iteration cycles from two or three weeks to three to five days, with tenfold evaluation throughput. The software did not supply medical judgment. It gave that judgment a route into the engineering pipeline.
“SuperAnnotate enabled us to transform deep medical expertise into scalable, structured ground truth data.”Roman Bugaev, CTO, Flo Health
The price of a second opinion
What does it cost? SuperAnnotate publishes Starter, Pro and Enterprise plans, but no public dollar prices for the latter two. Customers’ case studies offer a better view of where the money goes. At Wizard, an AI shopping agent, a fully manual review process was accurate but expensive as query volume rose. The team built a hybrid system with SuperAnnotate and an NVIDIA Nemotron judge: the model scored routine recommendations, while uncertain cases went to people. Wizard reported a 75% reduction in weekly annotation costs, 96% residual accuracy, and 91% agreement between the judge and human experts. Those are one customer’s results, achieved with its own queries and rubric, rather than a universal discount on human work.
Figures are reported in the respective companies’ published SuperAnnotate case studies.
Superhuman’s arithmetic was different. Its team had a homegrown evaluation tool, but new products, languages and formats pushed against it. Creating and changing jobs required knowledge of a custom markup system; engineers were carrying a queue of work that linguists and product teams could not easily do themselves. Superhuman evaluated several SaaS platforms, then chose SuperAnnotate partly because a pilot preserved the look of its own user interface inside the review tool. The company says the switch returned roughly 20 engineering hours a week while maintaining a 24-hour internal evaluation target. A replacement that had made reviewers judge an artificial version of the product would have missed the point.
The benchmark is a human artifact
One of SuperAnnotate’s more revealing jobs was OfficeQA, built with Databricks from roughly 90,000 pages of U.S. Treasury Bulletins. Old scans, revised figures and dense tables make easy-looking questions treacherous. Experts wrote questions whose answers depended on the documents and a second expert checked each item. The finished benchmark has 246 questions. In the company’s account, human solvers took about 50 minutes per question on a representative sample. That is a great deal of careful labor behind a neat score on a chart.
This is where SuperAnnotate sits in the market. It is neither a foundation model maker nor merely a pool of labelers. It sells a place to specify a task, recruit or manage people for it, inspect disagreements, keep an audit trail, and return the result to a training or evaluation system. The platform competes with products such as Labelbox, Scale AI, Dataloop and Encord, as well as tools built by customers themselves. Its managed expert network gives it another way into jobs where the hardest input is qualified judgment.
The logic has limits. A small, occasional labeling job with stable instructions may be cheaper to run in a sheet; SuperAnnotate says as much in its own guide to annotation tools. A model judge is useful only when people have first made a trustworthy reference set and keep checking its mistakes. If the rubric is vague, routing can scale confusion as efficiently as it scales review.
The company raised $36 million in a 2024 Series B and added $13.5 million from Dell Technologies Capital in 2025. Funding helps buy time to build software and recruit expertise; it does not settle the question that produced the company. It began with an edge in an image. Now, as more businesses buy AI that writes, recommends and acts, SuperAnnotate sells a disciplined way to ask where the edge of a correct answer lies. Copy the modest version first: write down the standard, have two informed people apply it, and look closely at the cases where they disagree. Those disagreements are often where the useful data starts.