In July 2021, Prolific got something most startups would celebrate: a rush of new users. An unaffiliated TikTok video recommended its paid studies as a side hustle. About 30,000 people signed up, heavily skewed toward women in their twenties. Researchers soon noticed their samples changing. The marketplace had attracted people willing to answer questions. The trouble was which people.
- Prolific finds paid participants for research and AI evaluation.
- You choose the audience; fast responses alone do not make a representative sample.
- Self-service pricing adds a platform fee to participant rewards.
The crowd that arrived all at once
The first thing to break in this episode was an assumption: an unscreened crowd would stay roughly familiar. Prolific offered platform-fee credits to qualifying affected studies, temporarily made representative sampling free, and promised easier demographic balancing. Complaints from researchers changed the product agenda.
Here is a lesson worth keeping: growth changes the thing you sell. A research marketplace sells access to a population. When that population changes, the answers change with it.
A scientist’s very practical problem
The company began with a smaller frustration. During her psychology PhD at Sheffield, Ekaterina, known as Katia, Damer struggled to recruit participants through a flexible, transparent online service. She and Phelim Bradley founded Prolific in 2014. Bradley built the first platform, became CTO, and took over as CEO in 2021.
The workflow remains pleasingly ordinary. Build a survey or experiment in another tool, such as Qualtrics or Gorilla. Connect its URL to Prolific. Choose participants using audience filters, set the reward, collect responses, then review and pay. The researcher supplies the question; Prolific supplies recruitment and the machinery around it.
That division matters. A behavioral scientist can run an experiment; a product team can test an idea; an AI developer can ask people to judge model outputs. Publicly named customers include Google, Oxford, Stanford and the European Commission. The work differs, but each customer needs people whose responses are useful for a particular purpose.
The bill belongs in the experiment
Imagine a ten-minute study with 100 participants, paid at Prolific’s recommended $12 an hour. Each earns $2. The reward budget is $200. At the standard academic rate, the platform fee adds about $66.67; at the corporate rate, about $85.71. Those are worked examples, before any applicable VAT.
The platform requires at least £6 or $8 an hour and recommends £9 or $12. Specialized work can justify more. Participants receive the reward you set; the fee sits on top. There is no monthly subscription for self-service access. Managed projects get custom pricing.
For a researcher, underestimating completion time makes the neat budget misleading. Pilot the task, time it honestly, and leave room to adjust payment. Paying for attention starts with respecting how long attention takes.
The waiting room earns its keep
Today, Prolific treats admission as part of quality control. Its Protocol system combines identity verification, continuing fraud checks, in-study safeguards, performance history and participant engagement. The company says waitlist invitations are shaped by demand. Letting everybody in immediately would make those controls harder to maintain.
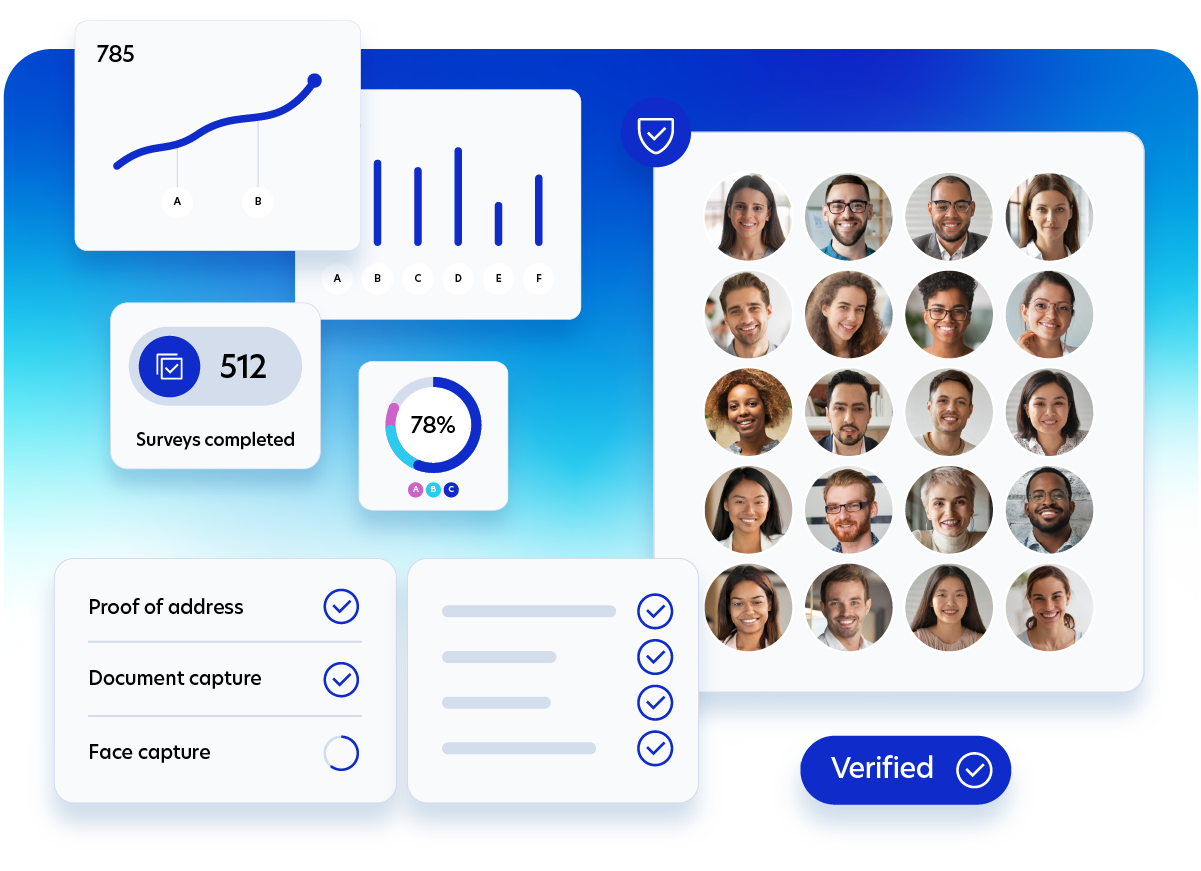
“Our ultimate ambition is to become synonymous with online research.”
Phelim Bradley, quoted on Prolific’s press page
There is evidence behind the positioning, with qualifications. A comparison published in Behavior Research Methods found high data quality on both Prolific and CloudResearch when filters were applied. Prolific-affiliated researchers were among its authors. A later correction addressed a technical error without changing the broad conclusions. It is useful evidence about tested conditions, rather than a permanent league table.
CloudResearch, Qualtrics panels and Dynata offer alternatives in online research. Prolific’s particular proposition is direct control over a vetted participant pool, alongside payments and quality tools. Its published culture prizes transparency and collaboration. Those principles face a practical test whenever a researcher’s deadline meets a participant’s time.
Now the machines need a second opinion
In July 2023, Prolific announced £25 million in funding, co-led by Partech and Oxford Science Enterprises, to expand its AI offering and US presence. The connection is straightforward: judging machine-generated answers needs many of the same recruitment skills as studying human behavior.
AI Task Builder, launched in early access in December 2024, brings datasets, instructions and human annotations into one workflow. APIs automate collection. AI Taskers are assessed for evaluation work; Domain Experts add professional knowledge. In August 2026, Prolific described access to more than 20,000 credentials-checked healthcare professionals across over 35 specialties.
A Prolific case study from September 2025 describes an unnamed AI company needing thousands of factuality evaluations within tight deadlines. Prolific combined assessed taskers, weekly feedback, targeted training and API integration. The company reports a tenfold acceleration. The instructive detail is the repeated calibration: recruiting people was only the beginning of getting consistent judgments.
A September 2026 demo goes further. Its trajectory tools capture how humans and agents complete tasks, using a shared data format. A trip-planning agent spends more than half of its 167 steps recovering from trouble, including a broken date picker. A final answer would conceal that expensive wandering.
Choose the audience before the answer
The move into AI raises the stakes of an old sampling question: whose judgment counts? Ordinary users can assess an experience. Trained raters can apply a rubric. Specialists can catch errors that other people miss. Choosing among them is part of designing the work.
For a first project, make that choice explicit in the study brief. Describe who should participate and what would count as a useful response. Run a small pilot before committing the full budget. Look for confusing instructions, unexpectedly long completion times and answers that expose a mismatch between the audience and the task. Those checks cost time upfront; they also give you a chance to fix the question while it is still cheap to change.
Prolific’s network does not automatically represent everyone. An opt-in online pool cannot replace field observation, and a rare audience may require custom recruitment. A badly worded task remains badly worded after 100 people complete it. Start with the population you need, test the instructions, inspect the sample, then interpret the answers. The 2021 surprise is a useful reminder to look at who arrived before celebrating how quickly they came.