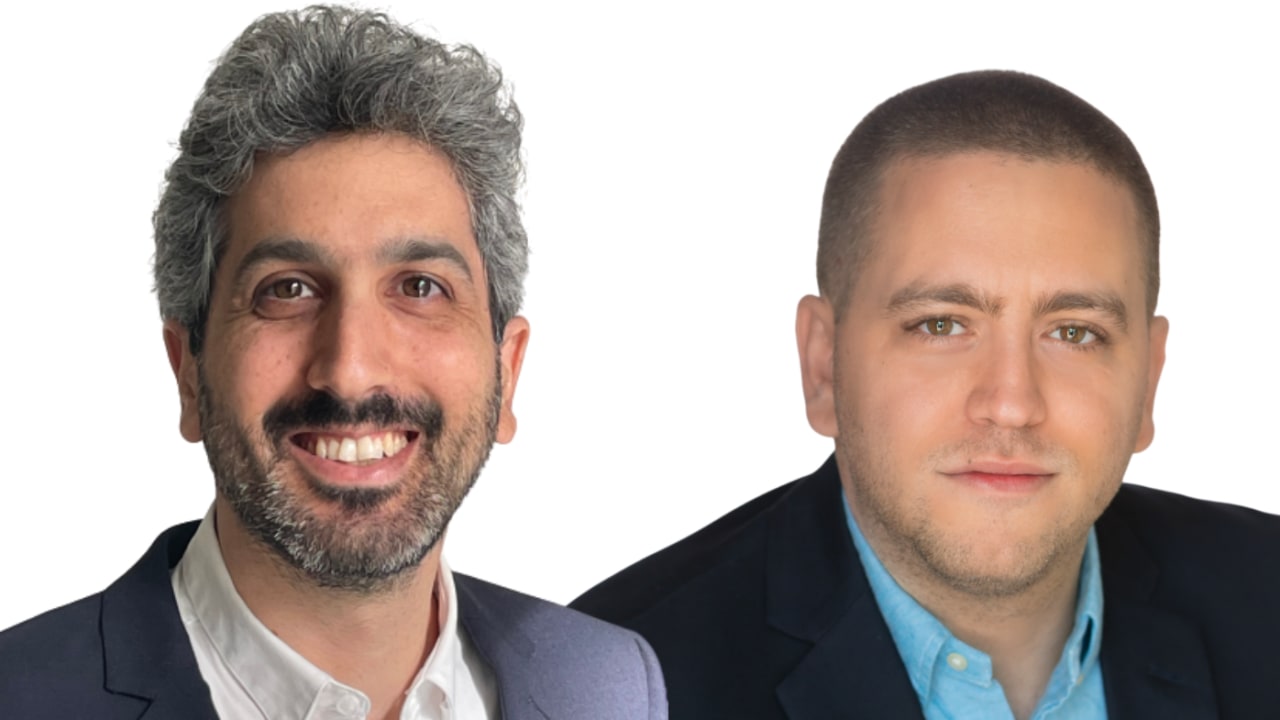
Ori Rafael’s problem was a calendar problem. He and fellow database engineer Yoni Eini wanted to store data affordably in the cloud and remain free to choose their analytics tools. Then they discovered how much work came with that freedom. A task that felt like a few hours in SQL could become a month of engineering. The storage was reasonably priced. The delay was harder to admire.
They founded Upsolver in 2014. Its premise was unusually easy to understand for a company dealing in data infrastructure: people who knew how to work with databases should be able to do useful work with a data lake, too. A new architecture ought to give them more possibilities without confiscating their working week.
That complaint would carry Rafael through a decade of product building, funding rounds and changes in the data industry’s preferred vocabulary. In January 2025, Qlik acquired Upsolver. Rafael’s title changed from startup CEO to an engineering role inside a larger software company. The original question remained recognisable: how much effort should stand between having information and using it?
A database education, then a company
Rafael studied computer science at the Technion and later earned an MBA at Tel Aviv University. His early professional education included seven years in Israeli intelligence, working as a database administrator, a development team leader and a leader of data-integration platforms. These were jobs in which information had to be organised and delivered, rather than merely collected.
He met Eini in the military. Their eventual partnership joined two people familiar with databases and the difficulties of managing large amounts of information. The origin matters because Upsolver began with users who already had technical skills. Their problem was the extra machinery required to apply those skills in a different environment.
While working on advertising optimisation, they became absorbed in the reliability, performance and scaling problems surrounding data lakes. That work led them toward data pipelines: the processes that prepare and carry information from one place to another. Instead of treating the complexity as an entrance examination for customers, they made reducing it the product.
The expensive part of cheap storage
A data lake offers somewhere to keep large amounts of information without committing everything to one database system. The attraction includes flexibility: different tools can work with the stored data. But the work required to turn that collection into reliable material for analysis can be considerable. A bargain warehouse is less delightful if every visit requires assembling the forklift.
Upsolver publicly launched its platform in January 2018. Early users included Sisense, ironSource and SimilarWeb. These were businesses for which processing data was part of the working day. Rafael’s company was selling a way to manage that work with less specialised engineering between a question and its answer.
In October 2019, Upsolver announced SQL-based ETL for cloud data lakes. ETL means extract, transform and load: retrieve information, prepare it and deliver it where it can be used. SQL was already familiar to database practitioners. Putting it in front of the process respected something customers had already spent time learning.
The choice also made the product’s argument concrete. A company could adopt cloud storage and tools such as Amazon Athena while giving more of its existing technical staff a way to participate. The engineering still had to happen somewhere. Upsolver’s business depended on making software carry more of it.
A conceptual map of the lakehouse work Rafael has focused on. It is an explanation of the architecture, not a performance comparison.
A company learns to grow
By June 2020, Upsolver had raised a $13 million Series A round led by Vertex Ventures US, with JVP and Wing Venture Capital participating. The announced plans included North American expansion, research and development, customer service and multi-cloud capabilities. The company had 22 employees, split between Israel and the United States.
There is a particular kind of growth hidden in those categories. A customer needs someone to explain the product, someone to help when it misbehaves, and someone to make it work in the environment the customer actually owns. A technically persuasive idea acquires a much longer list of duties when people begin depending on it.
In April 2021, Upsolver announced a $25 million Series B led by Scale Venture Partners. Existing investors participated again. The company reported that revenue had tripled in 2020. CTech put the team at 35 people and named Wix, AppsFlyer and Cox Automotive among customers added during that period.
Ariel Tseitlin, a Scale partner and former leader of Netflix Cloud Solutions, joined the board. Avner Gideoni joined as vice president of engineering. Around Rafael, the organisation was becoming more specialised. The founder who wanted to remove a technical bottleneck now had the familiar managerial task of ensuring that decisions did not all bottleneck at the founder.
His comments about leadership were candid. He wanted employees to challenge product decisions and treated disagreement as something to manage. He also distinguished an unsuccessful bet from poor communication around it. Failure could be tolerated; refusing to listen was another matter. The principle demanded a team willing to speak before a mistake became expensive.
“I wake up in the morning and fail twice.”Ori Rafael, 2021
During hiring, he described checking with former bosses, colleagues and direct reports. A hesitant answer to whether someone would hire a candidate again could carry considerable weight. The method was practical: listen closely to people who have already worked through the candidate’s ordinary Tuesdays.
The iceberg that helped the ship
Rafael also put the technical argument into print. In July 2022, O’Reilly published Unlock Complex and Streaming Data with Declarative Data Pipelines, which he co-authored with Roy Hasson and Rick Bilodeau. Its 37 pages covered changing data infrastructure, stream processing and alternatives for building pipelines.
The word “declarative” sounds forbidding for an approach intended to remove work. Its appeal is straightforward: describe the result you need and let the system handle more of the operational steps. The report’s subjects place Rafael’s company inside a wider question about how much infrastructure a data team should have to operate itself.
By 2024, Apache Iceberg had become central to his explanation of the opportunity. Iceberg is an open table format for analytics. It allows different processing engines to work with the same tables, while supplying capabilities associated with dependable database use. A shared format helps make a collection of files behave more like something people can confidently query.
The details matter. Tables change as new columns arrive. Records need updating or deleting. File layouts need attention if queries are to remain efficient. Iceberg provides common ways to handle these concerns across tools. Its usefulness comes from making agreement possible among systems that would otherwise need more bespoke arrangements.
At Upsolver’s Chill Data Summit in New York, Rafael and Eini discussed that opportunity with Ravit Jain. Rafael described a gap between having a standard and delivering the experience users wanted. Eini discussed the work involved in applying Iceberg to large-scale streaming. The format offered common ground; implementation still required care.
That distinction suited the company they had built. An open standard could widen the audience for Upsolver’s engineering rather than eliminate the need for it. Rafael’s original frustration concerned the labour around data. A standard made it possible to tackle that labour on terms more participants could share.
The question survives the acquisition
When Qlik acquired Upsolver in January 2025, the attraction was specific: real-time ingestion and Iceberg optimisation. Qlik could combine those capabilities with its existing data-integration platform. For Rafael, the combination offered a way to carry the work into more companies, with a broader set of connections to the systems those companies already used.
At Qlik Connect in May, he appeared alongside Sam Pierson as Qlik’s Senior Director of Engineering. The conversation concerned Open Lakehouse and the integration of Upsolver’s technology. It was a continuation with a different organisational setting: the same ingestion and management problems now sat inside a larger range of data tools.
Qlik Open Lakehouse became generally available on September 16, 2025. The service brought managed Iceberg capabilities into Qlik Talend Cloud, with deployment in a customer’s own cloud account and support for multiple analytics engines. The following days brought another public discussion, with Rafael and Pierson joining Chris Evans to talk through an open lakehouse strategy.
“Open” can sound like a philosophical preference. Here it concerns practical choices about where data lives and which tools may work with it. Keeping those choices available is part of the product. Making them manageable is the other part. Rafael’s career has repeatedly returned to the point where a technical possibility becomes someone’s daily responsibility.
The result is a founder story with an unusually durable complaint. New formats arrive. Products acquire new names. A startup becomes part of another company. Somewhere, a person still has a question to answer and would prefer to get on with it. Rafael’s work has been to shorten the journey between the two.
Continue the conversation
- Qlik
- Ori Rafael on LinkedIn
- Watch: Rafael and Sam Pierson at Qlik Connect
- Listen: the open lakehouse conversation
- Read: the 2022 O’Reilly report
- The 2021 funding announcement
- The Upsolver acquisition announcement
- Qlik Open Lakehouse availability
- The 2021 leadership conversation
- The Chill Data Summit conversation