- DataHub maps an organization’s data, owners, definitions, quality signals and lineage in one metadata graph.
- The free, open-source Core is self-hosted. DataHub Cloud is managed enterprise software with custom pricing.
- The company says 3,000+ organizations use the project; its community has 16,000+ members.
- Its newest customer is not a person at all: the AI agent that needs to know which table and metric to trust.
The trouble began with a crawler. At LinkedIn, the first metadata portal was called WhereHows, a name with the cheerful confidence of a tool that promises to tell you where the data lives and how it got there. It worked - until the company’s data estate outgrew the idea behind it. Every system needed its own crawler. Every crawler needed care. The central team became a customs office for a country adding a new border crossing every week.
There was another problem. WhereHows had opinions about what a dataset or job ought to look like. Those opinions hardened into its interfaces and storage. As LinkedIn collected metadata about metrics, charts, machine-learning features, people and policies, the tidy catalog became a badly packed suitcase. Privacy obligations, including GDPR work, made the limitations urgent. The system that was supposed to explain the data could not evolve as quickly as the data did.
So LinkedIn’s metadata team did the expensive, unfashionable thing: it went back to the drawing board. The new system would accept metadata pushed as events, rather than depend on a central fleet pulling from every source. It would model relationships in a graph. It would be general enough to represent new kinds of assets without another architectural renovation. They called it DataHub.
“Push is better than pull.”The architectural lesson LinkedIn carried from WhereHows into DataHub
The small failure that designed the big product
This is the useful part of the origin story. DataHub did not begin with a workshop about “unlocking value.” It began with specific machinery that had become painful. Shirshanka Das, then LinkedIn’s big-data architect, led the project. By 2019, LinkedIn said DataHub was indexing tens of millions of metadata records, spanning nineteen kinds of entities. It was used weekly by more than 1,500 employees and mapped over a million datasets.
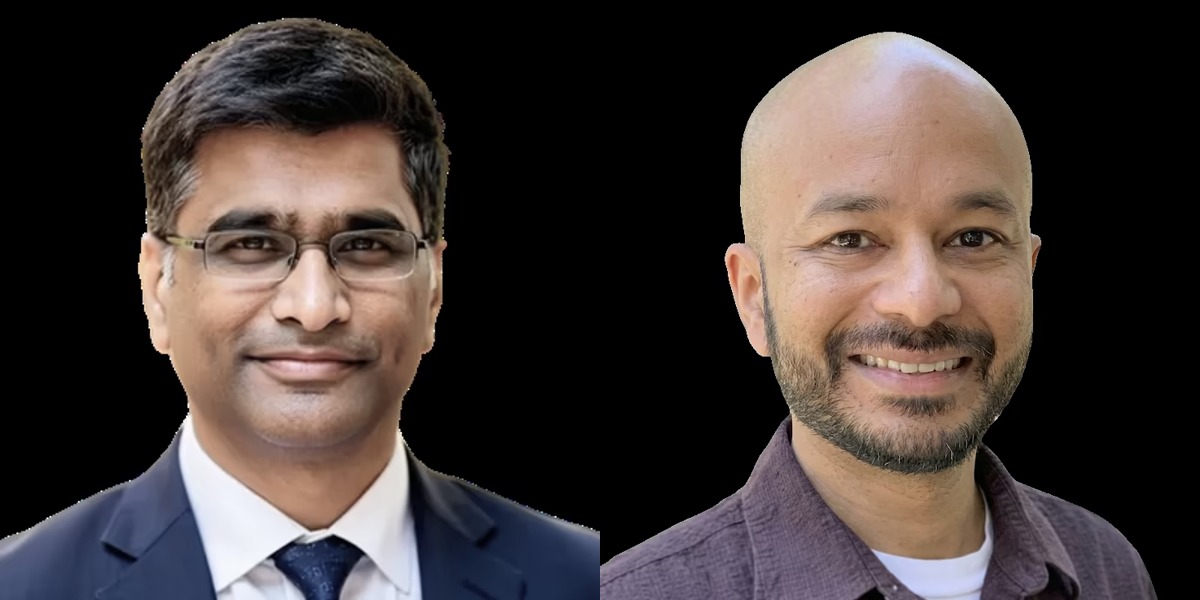
LinkedIn released the platform as open source in 2020. A year later Das and Swaroop Jagadish, the former head of data platform and search infrastructure at Airbnb, formed Acryl Data around it. Jagadish had helped build Airbnb’s DataPortal and standardize business metrics during the company’s run toward an IPO. One founder had watched metadata become essential to privacy and discovery; the other had watched it become essential to agreeing on what the business meant. Today Jagadish is CEO, Das is CTO, and the company trades simply as DataHub.
A catalog is a map. DataHub wants a nervous system.
A conventional catalog answers a librarian’s questions: What do we own? Where is it? Who is responsible? DataHub answers those too. It ingests metadata from warehouses such as Snowflake and BigQuery, lakehouses such as Databricks, orchestration tools, BI dashboards, streaming systems and machine-learning platforms. A user can search for a dataset, inspect column-level lineage, see whether it is fresh, find its owner and assess what might break if a field changes.
The graph is DataHub’s organizing advantage. A row in an inventory can tell you that a table exists. A relationship can tell you that the table feeds a metric, the metric feeds a dashboard, and the dashboard belongs to a team that will be surprised on Monday morning. Competitors including Atlan, Alation, Collibra and Microsoft Purview approach similar enterprise problems; OpenMetadata and Amundsen offer open-source alternatives. DataHub’s pitch is unusually engineering-led: event-driven ingestion, an extensible model and cross-platform lineage on the same foundation used by its open-source community.
The products divide neatly. DataHub Core is the Apache-licensed project a team can run itself with Docker or Kubernetes. It covers discovery, lineage, governance, profiling and contracts. DataHub Cloud runs on the same metadata model but adds managed operations, security controls, deeper automation, observability and support. Existing metadata work can carry over rather than being rebuilt.
You run the infrastructure, upgrades, reliability and support. Best for teams with the engineering time to own the platform.
Managed SaaS priced by environment, data volume, users and capabilities. DataHub does not publish a standard rate.
The new power user does not drink coffee
In 2025, DataHub’s language changed. The catalog became an “AI and data context platform.” This could have been a cosmetic brush with the fashion of the year, except the product logic is sound. An analytics agent can generate impeccable SQL against the wrong table. It can use last quarter’s metric definition with great confidence. A language model knows language; it does not automatically know which of six revenue fields the finance team blessed on Tuesday.
DataHub’s Context Platform, moved into public beta in September 2026, sits between agents and enterprise data. It ingests metadata from more than 150 sources, extracts meaning from query history and other technical traces, sends machine-generated context to domain experts for review, then serves the validated result through MCP. Ask DataHub provides a conversational interface in the product and Slack. Private-beta agents can handle documentation and governance chores, with pauses for human judgment.
This is a more interesting ambition than conversational search. DataHub is attempting to turn institutional memory into an API. The glossary entry, the query people actually use, the lineage path, the data-quality result and the owner’s correction become one package. An agent can retrieve not only a table, but the reasons to trust it.
The measurable wins are pleasingly unromantic
The best evidence for a catalog is not the number of assets inside it. It is what someone can do on Friday that was miserable on Thursday. DPG Media used DataHub’s metadata tests and impact analysis to identify unused or duplicate Snowflake tables, then reported cutting monthly warehouse costs by 25 percent. Foursquare, dealing with systems inherited through acquisitions, said data discovery and access fell from days to minutes. Its team automated metadata capture around Airflow and used lineage as part of a broader developer journey.
These examples reveal what readers can copy. Start with one expensive experience, not a company-wide command to “do governance.” Pick the first journey worth fixing: finding a trusted dataset, tracing a broken dashboard, retiring redundant tables or proving who owns sensitive fields. Instrument metadata at the source. Make lineage part of pipeline work. Give each domain an owner. Measure elapsed time, incidents or cloud spend before inviting the entire company to admire the catalog.
The clever metric is not “assets cataloged.” It is “questions no longer routed through one exhausted engineer.”
What the $65 million is buying
Acryl Data emerged from stealth in 2021 with a $9 million seed round led by 8VC. A $21 million Series A followed in 2023. In May 2025, Bessemer Venture Partners led a $35 million Series B, bringing disclosed funding to $65 million. The money supports an open-core bargain: the community gets a substantial free platform; enterprise customers pay to avoid running it and to gain controls, automation, support and service commitments.
That bargain also explains the community’s strategic value. DataHub says the project now reaches more than 3,000 organizations, 16,000 community members and three million monthly Python-package downloads. Apple, Netflix, Visa, Figma and LinkedIn appear among prominent users. The public project gives engineers a low-friction way to test the architecture, creates a large base of integrations and skills, and makes the commercial product less of a blind date.
The conditions that matter
DataHub works best when a company has enough systems and cross-team confusion to justify a shared map, plus engineers and stewards willing to maintain ownership and definitions. It is a weak fit for a small stack with obvious sources, no governance owner or no appetite for operating Core. Cloud removes infrastructure work, not the human work of deciding what “revenue” means. If nobody is accountable for that meaning, the graph will faithfully automate the ambiguity.
The catalog learned a second job
DataHub’s evolution has a satisfying symmetry. WhereHows failed because a central team could not manually keep pace with changing systems. DataHub answered with events, extensibility and distributed contributions. Now AI agents create the same problem at another order of speed: more questions, more automated actions and more opportunities to use the wrong thing confidently. The company’s answer is again to make context continuous and machine-readable.
The category name may keep changing - catalog, control plane, active metadata, context platform. The underlying job is steadier. Every serious data organization needs a memory of what its information means, where it came from and who will notice when it changes. DataHub’s wager is that this memory should not sit in a wiki waiting to be forgotten. It should move with the data and answer back.
Keep exploring
- Visit DataHub or compare Cloud and Core.
- Browse the open-source repository and technical documentation.
- Follow DataHub on LinkedIn and X.
- Watch product demos, town halls and interviews on the DataHub YouTube channel.