Long before Prashant Shishodia began teaching machines to handle the texture of a human voice, he was a student trying to locate the machinery of opportunity. His school was Jawahar Navodaya Vidyalaya in Bulandshahar, Uttar Pradesh. In a short account preserved by the Dakshana Foundation, he described arriving in class IX with little awareness of IIT, competitive examinations or the coaching economy built around them. Mathematics caught his attention. A scholarship gave that attention somewhere to go.
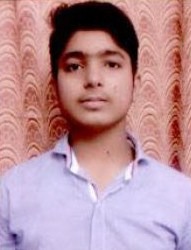
The ambition in his student note was plain: he wanted to attend IIT and become an engineer. Dakshana selected him for its JEE 2017 cohort at JNV Kottayam, providing coaching he wrote that he could not otherwise afford. In 2017, he earned All India Rank 219 in JEE Advanced. IIT Kharagpur admitted him to computer science and engineering. Four years later, Google hired him.
This is a tidy sequence only when viewed backward. Living through it would have felt more granular: a stronger mathematics foundation, a competitive exam, a university roll number, the first programming problems that refused to behave. An old Stack Overflow account still shows two questions from 2018, both ordinary student puzzles in C++. One concerns priority queues. The other concerns a numeric conversion. Every large technical career contains a small argument with a compiler.
The education of a scaling engineer
At Google, Shishodia spent four years close to systems whose scale can turn a minor inefficiency into an expensive habit. His personal account divides the work into two chapters. First came Local Ads, where he worked on retrieval strategies and credited the work with substantial annual revenue impact. Then came Google Assistant and Home Intelligence, where the questions shifted toward model quality, training, evaluation and serving.
The number attached to that second chapter is roughly 10 billion queries a month. Serving models at that volume is less like staging a clever demo and more like running a utility. Compute is finite. Latency is visible. A model that is marginally better but impossible to operate is a research result, not yet a product. Shishodia says the work included making smaller Gemini variants efficient enough to handle billions of monthly queries with limited TPU capacity.
That discipline continued outside the immediate product work. Shishodia became a co-author of research on ternary language models, systems that constrain weights to three values to reduce memory demands. The paper studied how those models scale and introduced packing methods and inference kernels designed to make them faster on CPUs and GPUs. It appeared as a long paper at ACL 2025.
The subject sounds distant from a voice startup until one notices the shared preoccupation. How do you preserve capability while reducing the cost of using it? Efficiency, in this view, is not housekeeping performed after the interesting work. It decides which interesting work can leave the lab.
A smaller project from this period offers another clue. Shishodia built Husn, a fashion discovery product that searched millions of items by “vibe” rather than forcing shoppers through rigid catalog filters. The project appeared on the web, Android, iOS and GitHub. Fashion search and speech generation share little at the surface. Underneath, both ask software to translate a fuzzy human instruction into something a machine can retrieve or create.
“Vibe” is an imprecise word with precise consequences. A shopper may know the feeling of an outfit without knowing the merchant's taxonomy. A caller may hear irritation in a voice that a transcript labels as an ordinary sentence. Shishodia's projects keep circling the distance between what people mean and what conventional interfaces require them to specify. Better models can narrow that distance, but only if the surrounding system is fast enough to stay out of the way.
“Speech is where text was in 2019.”Prashant Shishodia, on the opening he sees in audio models
A disagreement with the voice stack
Kalpa Labs began in 2025 with Shishodia as CEO and Gautam Jha as CTO. Jha brought experience building nanosecond-latency infrastructure for high-frequency trading. Shishodia brought full-stack machine learning at Google scale. Y Combinator placed the company in its Fall 2025 batch. The official directory listed a team size of two in San Francisco, which makes its chosen problem seem almost mischievously broad.
Their disagreement is with specialization. A modern voice product may send audio through speech recognition, pass text to a language model, then send the answer into a speech generator. Add separate systems for voice cloning, dubbing, music or editing. The chain works, but each handoff can discard information. A transcript records the words while shaving away hesitation, rhythm, emphasis and mood. The final voice may pronounce the answer fluently while missing the emotional weather of the exchange.
Kalpa's answer is a generalist audio model: one system intended to follow detailed instructions, learn from examples placed in context and cross the borders between recognition, generation, cloning and other audio tasks. The company described pretraining models from 800 million to 4.8 billion parameters on roughly two million hours of mixed-domain audio. It also said its architecture reduced the cost of long audio, a necessary move if models are to remember more than a brief exchange.
There is a product idea hidden inside the research vocabulary. People do not begin every sentence as strangers. They accumulate context. They notice whether a joke landed, whether a name was corrected three minutes ago, whether the room has become tense. A useful voice agent needs some version of that continuity. Otherwise, every response arrives wearing the same immaculate but inappropriate suit.
The neglected languages in the room
Shishodia has also made the data problem unusually specific. In late 2025, he publicly asked, “Who's building ScaleAI for India?” and said Kalpa Labs expected to spend $500,000 on data over six months, with a significant portion directed toward India-specific needs. His complaint was practical: high-quality Indic data is scarcer, and the tools needed to identify, clean and transcribe it are weaker than their English-language counterparts.
For a company invoking generalism, that gap is not a charitable side project. A model cannot plausibly be general if widely spoken languages arrive as thin datasets and brittle preprocessing pipelines. Accent adaptation is not a decorative feature either. It changes whether a system hears a person as expected input or as an exception requiring apology.
The concern connects neatly, though not sentimentally, to Shishodia's own route. His education moved through a public residential school, scholarship coaching and IIT. He knows what happens when talent is abundant but infrastructure is unevenly distributed. Now the infrastructure is data, annotation, language identification and audio quality. The entrance examination belongs to the machine, and some languages have been handed a thinner textbook.
From thesis to a voice that talks back
By August 2026, Kalpa Labs had moved its conversational speech model into public beta. The release offered three doors: a Studio for directing multi-speaker scenes, a live browser conversation and an API. The company reported a time to first audio of 300 milliseconds and published blind preference results against two ElevenLabs models. Those are company measurements, useful as a marker of what Kalpa values: response speed, naturalness and sustained quality.
The broader model remains a research direction rather than a finished destination. Kalpa calls it a Generalist Audio Model, or GAM: a unified system able to follow complex instructions and learn from in-context examples. The company imagines tasks that would be awkward for a chain of narrow tools, such as continuing an expressive performance, steering delivery through a long prompt or moving across speech understanding and generation without losing the thread.
Shishodia's public writing has the impatient cadence of an engineer who believes an old abstraction has expired. Yet his more revealing observation concerns limits. In a 2026 panel on data work, he argued that when a model confronts genuinely novel work, human involvement has no real substitute. It is a useful constraint for someone building toward more capable models. Generality is a direction, not permission to pretend the unknown has vanished.
There are now several versions of scale in his story. The teenager discovers the national machinery of an entrance exam. The graduate encounters a search and assistant infrastructure measured in billions. The researcher asks how to pack model weights into fewer bits. The founder trains across millions of hours of audio, then listens for details a transcript would throw away.
What joins them is an appetite for leverage without a romance about waste. Build the larger idea, certainly. Then make it fit through the world: through the available compute, the latency budget, the data pipeline, the browser call and the many accents waiting on the other end. A machine may speak after 300 milliseconds. Understanding why the voice matters has taken Shishodia rather longer, and the work is still talking back.