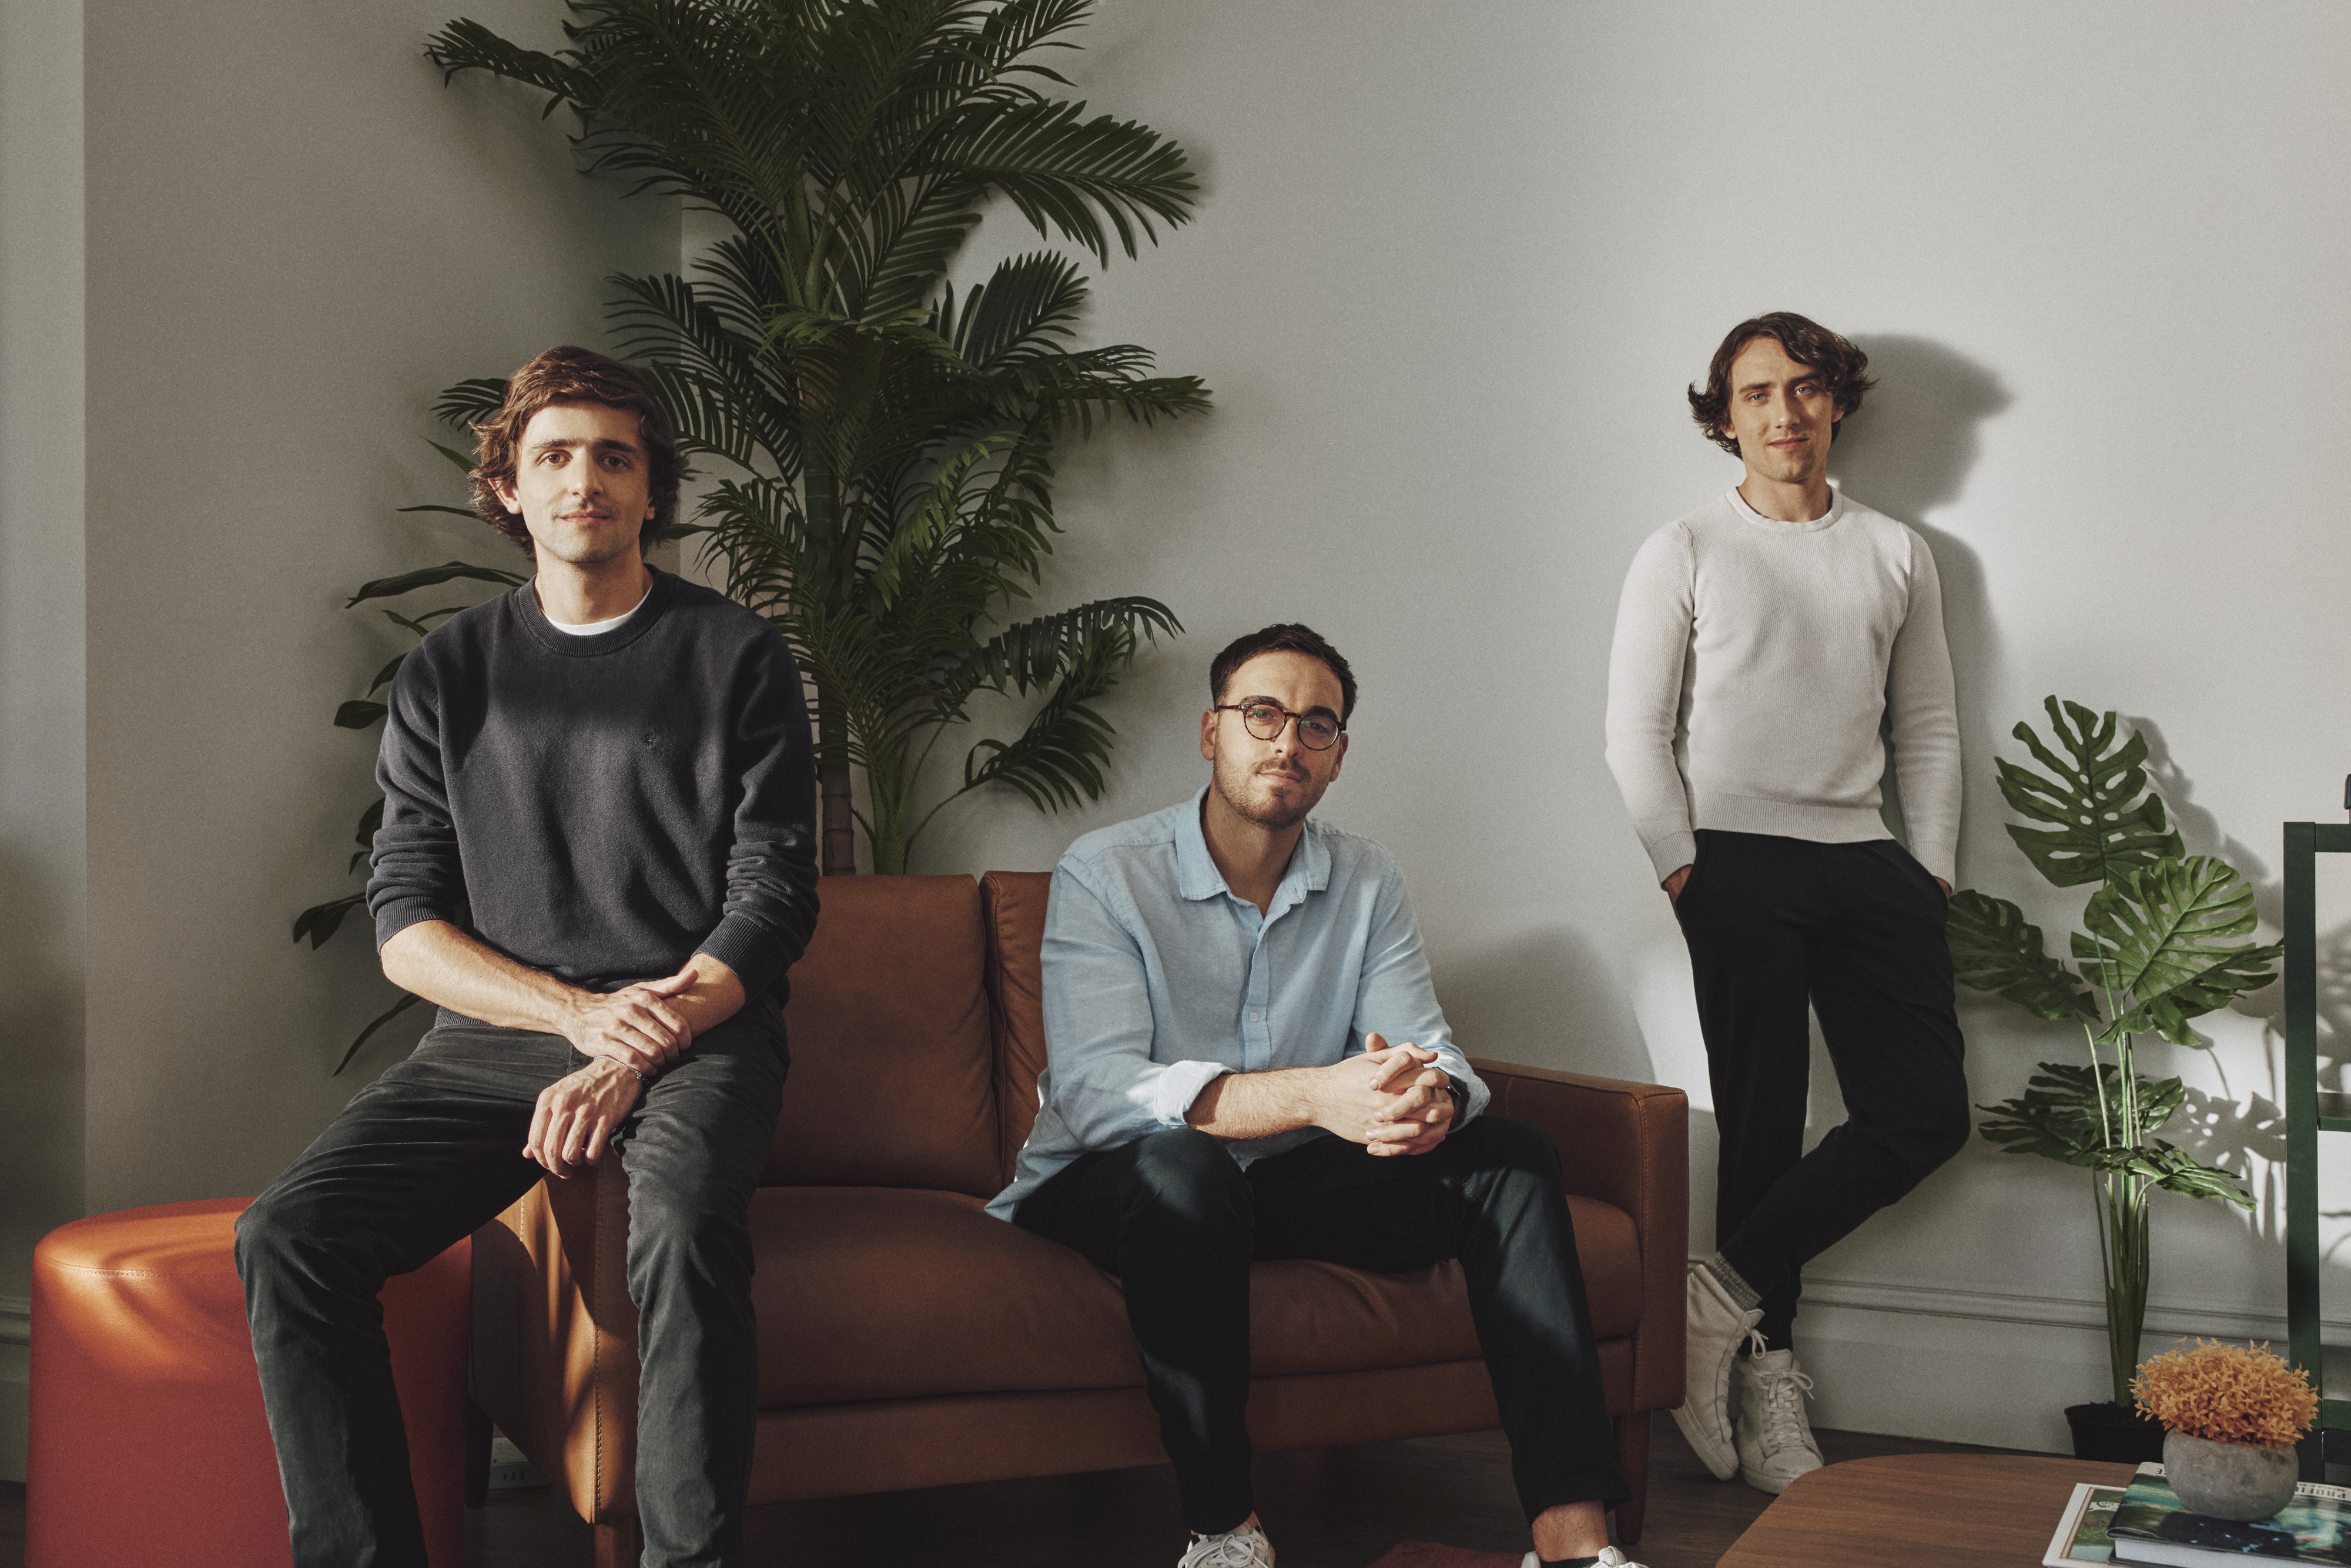
The troublesome part of a chatbot is often everything that happens before the chat. Caleb Peffer, Eric Ciarla and Nicolas Silberstein Camara learned this while building Mendable, a product that let companies answer questions from their documentation. Customers included MongoDB and Snapchat. The questions were reasonable; the source material was not. Documentation lived on sprawling sites, arrived wrapped in navigation and markup, changed without warning and sometimes required a browser merely to exist. A model could sound clever while answering from the wrong paragraph.
The three founders had a choice familiar to anyone who has built software: keep repairing the internal tool, or ask why everyone else appeared to need the same repair. In 2024, they made that repair the product. Firecrawl took a URL and returned clean material an application could use. By September 2026, the company said more than 1.5 million people were building with it. A small maintenance chore had found a rather large audience.
- Firecrawl turns web pages, sites and documents into structured material for AI agents and other software.
- Its customers range from chatbot builders to coding agents, researchers and sales teams.
- It sells a hosted, credit-based API alongside an open-source core.
- Alexandria extends the same interface to indexes, connectors and licensed data providers.
The question behind the question
Consider a support assistant asked whether a product works with a particular version of a database. The answer may be buried in a documentation page that loads with JavaScript. A conventional HTTP fetch finds little of use. A browser gets the page but also its menus, cookie notice and footer. A scraper finally extracts a paragraph, only for the publisher to update it next week. The model's reasoning is downstream of all these small, physical inconveniences.
Firecrawl's original proposition was to gather that inconvenience into one API. Scrape reads a known page; Crawl walks a site; Map finds URLs; Search discovers sources. Developers can request Markdown, HTML, screenshots or structured JSON. Later additions widened the job: Parse handles uploaded PDFs and office files; Interact clicks, types and navigates through a live browser; Monitor watches for changes. This is less romantic than an agent that writes poetry. It is also how the agent finds out whether the poem's subject closed on Tuesday.
The company reports that Replit uses its data to keep coding assistance current with documentation. Zapier lets customers feed public websites into its chatbots. Botpress uses it for knowledge bases; 11x uses search and crawling for prospect research. Those are different products, yet each faces the same question: can you get the right facts out of a changing source without hiring a team to babysit scrapers?
A business made of saved afternoons
Firecrawl's pricing gives a practical measure of the work. As of September 2026, a basic page scrape or crawl costs one credit. Ten search results cost two; a browser interaction minute costs two. The free plan includes 1,000 monthly credits, while the Hobby plan starts at $19 a month when billed monthly. A returned 403 or 404 page can still cost a credit. That is a small but important reminder: paying for access to a tool is not the same as obtaining permission or a useful answer from every site.
For a one-off, cooperative website, a script and an open-source crawler can be quite enough. Firecrawl earns its fee when a product needs many sites, predictable output, browser rendering, retries and ongoing maintenance. Its open-source stack covers the central scrape, crawl, map and search functions; the company says its managed anti-bot layer and several browser features belong to the hosted service. That division is the business model in miniature: developers can inspect and run the foundation, then pay to shed the operational burden.
The alternatives tell you where Firecrawl sits. Apify's marketplace offers site-specific automation. Tavily is oriented toward search and retrieval. Proxy companies such as Bright Data serve teams that want more control over the lower-level machinery. Firecrawl's pitch is a joined-up path from finding a source to cleaning it for an AI application. The attractive part is fewer moving pieces. The tradeoff is dependence on its formats, coverage and credit schedule.
“Even the strongest model can’t reason over information it never found.”Caleb Peffer, introducing Alexandria
The library gets a card catalogue
A website, however, is only one sort of knowledge. A research agent may need scientific papers; a financial one may need filings; a coding assistant may need the issue thread where a bug was fixed. By August 2026, Firecrawl had launched a Developer Index spanning more than 70 million documentation, README, issue, pull request and API specification artifacts. In September it announced Alexandria: a common interface joining the live web, specialist indexes, custom connectors and official data providers.
The move came with a $75 million Series B led by Smash Capital. Firecrawl had raised a $14.5 million Series A in 2025, when it said 350,000 developers had signed up and its GitHub project had passed 48,000 stars. The latest round is a bet that the problem is bigger than scraping. Firecrawl says Alexandria improved answer quality by 21% against built-in web tools on an internal, 845-task evaluation with the same model and prompts. That is the company's test, not an independent universal score. It does suggest what it is trying to sell: better source material before a model begins to answer.
The more unusual part is money flowing toward sources. Firecrawl says it pays Wikimedia Enterprise for direct Wikipedia data access and wants to open a broader system through which individuals, creators and organizations can earn when agents use their knowledge. This is still an ambition, not a finished market. Yet it addresses a tension that web scraping has long left to someone else: if the answer is valuable, what does the person who maintained the source receive?
The lesson hidden in the plumbing
There is a repeatable method in Firecrawl's beginning. Build a product for a concrete user. Notice which dependency keeps consuming your engineers' time. Check whether neighboring teams are rebuilding the same dependency. Then make the smallest useful version of that dependency available to them. Firecrawl did not begin with a grand library; it began with a chatbot that needed cleaner documentation.
The method has limits. If the source is private, legally restricted, unstable or simply absent, an elegant API cannot conjure it into existence. If a team needs a single friendly site, a hosted platform may be excessive. And if a model's question is bad, clean data will only help it answer the wrong question more efficiently. Firecrawl's achievement is narrower and more useful than magic: it reduces the number of ways good questions are defeated before the model ever sees the evidence.
The founders followed the mess upstream once, from chatbot to crawler. Alexandria is the next upstream turn, from pages to the people and institutions that know things worth retrieving. A library card is an appealing metaphor. The actual work is less picturesque: contracts, indexes, browser sessions, credits and a great many pages that insist on loading one second later. That, as it turns out, is a business.