Imagine a buyer opening a live shopping app on a Tuesday afternoon. A seller has just gone on air. The buyer watched a similar show two minutes ago. Yet the recommendation engine has a memory from Monday night. It can know the user's old tastes and yesterday's inventory, but the most interesting facts of this moment have not arrived. The model may be brilliant. Its briefing is late.
That was the practical problem behind a change at Whatnot, the live shopping marketplace. Its earlier system generated more than 10 billion predictions overnight. As shows and sellers multiplied, cold starts could delay personalization for about 24 hours, recent taps and chats were left out, and prediction coverage slipped toward 90 percent. An enormous amount of computation went into scores that nobody ever used.
- Chalk computes and serves model inputs, called features, using live and historical data.
- Whatnot uses it for feed ranking and show discovery; lenders use it for credit and fraud decisions.
- The trade is infrastructure complexity for fresher decisions, with an enterprise contract and integration work to match.
The answer has to arrive while the customer waits
Chalk sits between a company's data and the model that makes a decision. It connects to databases, warehouses, streams and APIs, then assembles the facts a model needs. In machine-learning language those facts are features: perhaps a customer's recent transactions, a show's current audience, or the number of failed logins from a device. The company calls its core product a feature store, but its defining idea is to compute some features when a query arrives instead of relying only on a cache prepared earlier.
That distinction sounds modest until a fact changes quickly. A fraudster can open several accounts in minutes. A shopper can move from browsing shoes to watching a vinyl auction in one session. A fresh signal has a short shelf life, and a warehouse batch is a poor clock for it. Chalk's platform lets engineers describe feature logic in Python, reuse those definitions for training and live serving, and ask for data as it would have appeared at a particular point in time. The latter matters: a model trained on facts that were unavailable when the original decision happened is a model taught by hindsight.
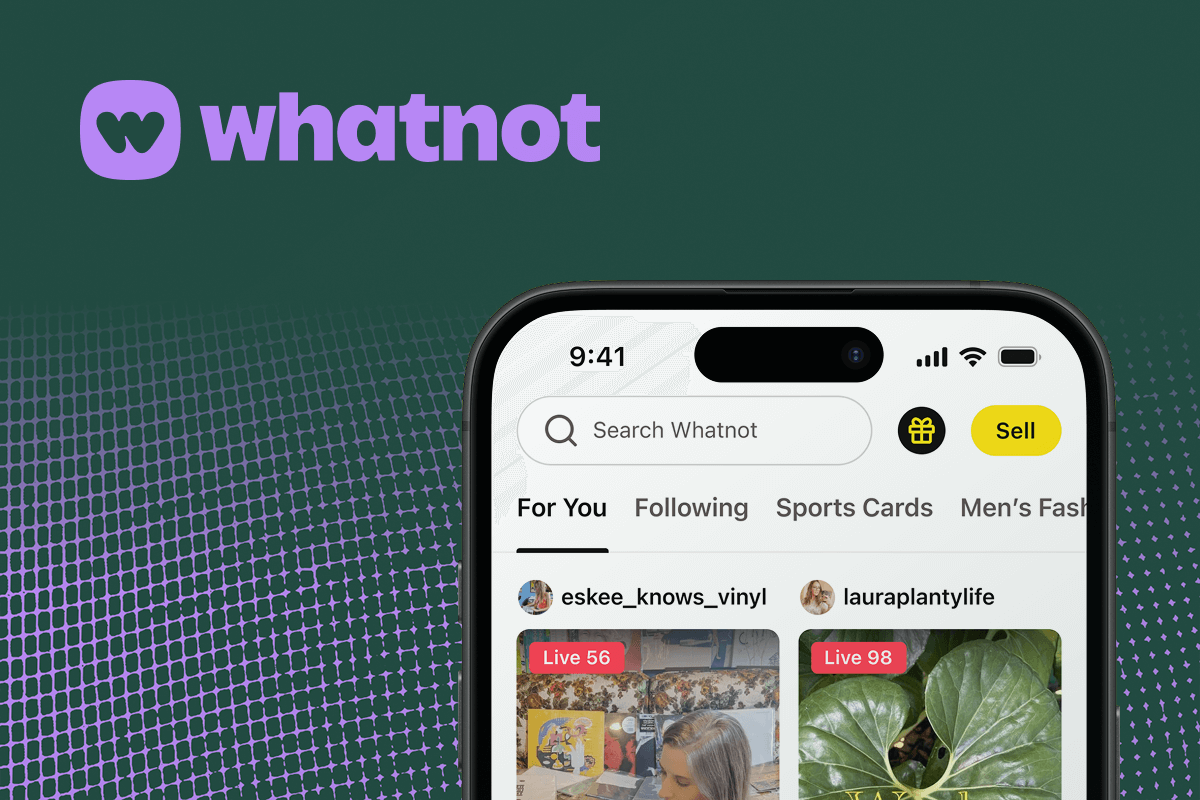
Whatnot made the architecture tangible. Chalk became both its store of reusable features and its online feature engine. The company says the new setup supplies tens of thousands of inputs for a request, drawing on current session activity and older history. In its published account, Whatnot reports more than 300 million features served per second, with roughly one-megabyte payloads and feature latency below 100 milliseconds at the 99th percentile. The entire feed decision, including work beyond Chalk, takes about 150 milliseconds. Those figures describe Whatnot's workload, rather than a universal promise for every deployment.
What failed before the model did
The first visible crack was coverage. Whatnot says its old system reached roughly 90 percent of users as scale and inventory increased. It also could not use recent session signals or greet a new seller promptly. The repair was not to train a bigger model and hope. It was to move feature computation nearer to the moment a person opened the feed. Cold-start delay fell from about a day to less than an hour, and the company says iteration moved from weeks to days.
This is a useful lesson beyond shopping. Before buying a new model, ask how old its inputs are, what happens to a new user, and how much work is spent scoring situations that never occur. Those questions travel easily from a live marketplace to a payment authorization or an emergency-room routing decision. They also tell you when Chalk's approach may be excessive: if the underlying facts hardly move, a simpler scheduled pipeline can do the job.
Three founders who had met the same nuisance before
Chalk's founders knew the problem from finance and infrastructure. Elliot Marx built early risk and credit data systems at Affirm. Andy Moreland worked on large data projects at Palantir; he and Marx later started Haven Money, acquired by Credit Karma. Marc Freed-Finnegan helped launch Google Wallet and founded Index, which Stripe acquired for what became Stripe Terminal. Their experience did not suggest a glamorous new species of algorithm. It suggested that the plumbing beneath models was still being assembled and reassembled by hand.
Marx has told a charming founding story: once he and Moreland decided Freed-Finnegan should lead the company, he drove from San Francisco to Los Angeles and stayed at his place until he agreed. He called it Chalk's first sale. The company began in 2022 and announced a $10 million seed round in 2023. A $50 million Series A, led by Felicis, followed in May 2025 at a stated $500 million valuation.
Chalk's name is an unusually candid clue to its character. It nods to the mathematician's chalkboard; the square in its logo borrows from the QED mark at the end of a proof. The company hires around systems engineering, query optimization and distributed processing. This is software for people who care where the milliseconds go.
A market of different clocks
The customer list explains why the pitch widened beyond fintech. Mission Lane uses Chalk for credit approvals and fraud detection, coordinating hundreds of interdependent features from bureau and internal data. MoneyLion uses it for fraud and personal-finance experiences. Melio applies it to risk on B2B payments. Turo uses it across search, pricing and risk; Medely uses it in clinician matching and shift pricing. Whatnot uses it for recommendations. The common market is not an industry label. It is any organization whose model's answer becomes worse as its inputs age.
Chalk competes with homegrown pipelines and feature stores, and with larger data and ML platforms such as Databricks and Tecton. Its argument is that one feature definition should work in a training set, a batch job and a live request, while the engine decides what to fetch or compute. Mission Lane's public demo shows the attraction: a model can ask for more than 300 features by name, while Chalk resolves the dependency tree. A data scientist can change the feature definition without asking three teams to rewrite the same idea in different systems.
There is a cost to that convenience. This is enterprise infrastructure, not a one-click browser toy. A buyer has to connect sensitive data sources, map definitions, test tail latency and operate a deployment. Chalk offers its own hosting or a self-hosted setup in the customer's cloud, and forward-deployed engineers to help. Its AWS Marketplace listing describes charges based on contract terms plus usage. Whether that beats an existing pipeline depends on query volume, engineering time and how much freshness the decision is worth.
A model can be accurate in the lab and still be late at the checkout.The practical case for fresh features
The feature store grows a memory
Since its Series A, Chalk has expanded the same time-centered idea into more of the ML stack. Chalk Compute, announced in June 2026, runs agent sandboxes inside a customer's cloud and can replay historical context for evaluations. September brought an MCP server, an in-product assistant and Chalk Notebooks. The notebooks query production-connected data and let a researcher compare a live deployment with a branch, including what was knowable at a specified time. A model experiment gets a record of its evidence, not just a promising chat transcript.
The expansion is ambitious, but the original question remains simple enough to copy. List each decision your system makes. Mark the newest fact it truly needs. Measure the age of the data it actually receives, the time it takes to return an answer and the work wasted on predictions no one requests. If those numbers look like Whatnot's old 24-hour gap, the trouble may be in the clock, not the intelligence. Chalk's business is selling a faster one.